

URCU-protected queues and stacks
The URCU library also provides RCU-protected queues and stacks, which are covered in the following sections. Following this is a discussion of queueing and real time.
Queues
Given that queues are inherently bottlenecks, it is well worth asking why any respectable parallel program would ever use them. One answer might be that each element on the queue represents such a large block of work that the synchronization overhead on the queue itself is negligible by comparison. Another answer might be that a large number of queues are used concurrently. For example, a multi-user parallel application might be structured as shown below:

Here, each user has a user-interface thread that communicates with the corresponding computation thread via input and output queues. Thus, the queue throughput scales with increasing numbers of users by adding queues. However, different applications need different things from their queues, and liburcu therefore provides two different flavors of queue, wait-free concurrent queues and RCU-protected lock-free queues.
Wait-free concurrent queues
The first flavor is wfcqueue, which provides concurrent access
with wait-free enqueues, at least on systems that provide an
atomic exchange instruction.
Dequeue operations are normally guarded by a lock and will wait for a
partially enqueued element to be completely enqueued, and hence are blocking.
However, there are non-blocking dequeue operations that, when constrained to
be executed by only a single thread, are lock-free.
The following include file provides the needed definitions:
#include <urcu/wfcqueue.h>
As with URCU, defining the C preprocessor symbol
_LGPL_SOURCE before the #include
enables static linking.
Static linking provides increased performance for those willing
to abide by its licensing and technical constraints.
The wfcqueue data structures are unusual in having a separate
structure for the queue head (struct cds_wfcq_head)
and tail (struct cds_wfcq_tail).
This separation allows the user to either cache-line align these
two structures or co-locate them, depending on the relative
importance of concurrent access on the one hand, and memory
footprint on the other.
Either way, a separate cds_wfcq_node structure
represents the queue's nodes, so that a user would embed
fields of type struct cds_wfcq_node in the data
structure that is to be enqueued.
The wfcqueue API may be found
here.
Note that wait-free concurrent queues are unusual in that queues can be merged
together using cds_wfcq_splice_blocking().
This allows O(1) operations to merge O(N) elements, for example,
when using queues to accumulate the result during the reduce phase of
a map-reduce operation.
RCU-protected lock-free queues
The second flavor is rculfqueue, which provides lock-free
concurrent enqueue and dequeue.
This is in contrast with wfcqueue, which provides
wait-free enqueue (on systems supporting an atomic exchange
instruction), but for which dequeues can block waiting for a partially
completed enqueue.
The following two include files provide the needed definitions:
    #include <urcu.h>
    #include <urcu/rculfqueue.h>
Once again, defining the C preprocessor symbol
_LGPL_SOURCE before the first #include
enables static linking.
Static linking provides increased performance for those willing
to abide by its licensing and technical constraints.
Unlike wfcqueue, rculfqueue uses only
a single structure to define a queue head and tail, namely
cds_lfq_queue_rcu.
Each element in a rculfqueue must contain a node structure
of type cds_lfq_node_rcu.
The rculfqueue API may be found
here.
Stacks
Of course, it is just as silly to run all the data processed by an otherwise highly parallel program through a single stack as it would be through a single queue. There are two flavors of stack, namely wait-free stacks and lock-free stacks.
Wait-free stacks
The first flavor is wfstack, which provides wait-free
pushes and blocking pops.
The pop operation can block waiting on a push to complete, and
furthermore the caller must ensure that only one thread attempts a
pop operation at a given time.
The following include file provides the needed definitions:
#include <urcu/wfstack.h>
Yet again, defining the C preprocessor symbol
_LGPL_SOURCE before the first #include
enables static linking.
Static linking provides increased performance for those willing
to abide by its licensing and technical constraints.
The cds_wfs_stack structure represents a
wfstack and the cds_wfs_node represents
a node that must be embedded as a field in the data element to be
pushed onto the stack.
There is also a cds_wfs_head structure that is used
by API members that pop all the elements from a stack in one go.
The wfstack API may be found
here.
Lock-free stacks
The lfstack flavor of stack provides lock-free
pushes and blocking concurrent pop and pop-all operations.
There are also special-purpose pop and pop-all operations with
reduced synchronization overhead.
The following include file provides the needed definitions:
#include <urcu/lfstack.h>
Older implementations have similar functionality in
urcu/rculfstack.h.
Yet again, defining the C preprocessor symbol
_LGPL_SOURCE before the first #include
enables static linking.
Static linking provides increased performance for those willing
to abide by its licensing and technical constraints.
The cds_lfs_stack structure represents a
lfstack and the cds_lfs_node represents
a node that must be embedded as a field in the data element to be
pushed onto the stack.
There is also a cds_lfs_node structure that is used
by API members that pop all the elements from a stack in one go.
The lfstack API may be found
here.
Queueing and real time
Real-time applications often are structured in a manner similar to biological central nervous systems, for example as shown in the following diagram, where the dashed box delineates the boundaries of the computer system:
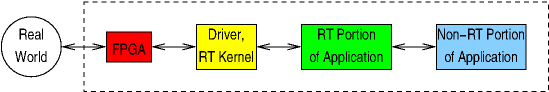
Here, the fastest response times (analogous to autonomic reflexes) are found in the FPGA. The next fastest response times (analogous to somatic reflexes) are found in the FPGA's driver within the -rt kernel, although Frédéric Weisbecker's NO_HZ_FULL work should allow the application to communicate directly with the FPGA with little or no interference from the kernel. The next fastest response times (analogous to a highly trained reaction) are found in the real-time portion of the application. Finally, the slowest response times (analogous to conscious thought) are found in the non-real-time portion of the application. One of the strengths of the Linux kernel with the -rt patchset is that the real-time and non-real-time portions of the application can be located not only within the same operating-system instance, but also within the same multithreaded process.
This raises the question of how the real-time and non-real-time portions of the application can communicate without imposing latency risks on the real-time portion. We can answer that question by zooming in on the boundary between the real-time and non-real-time portions of the application, as shown below:
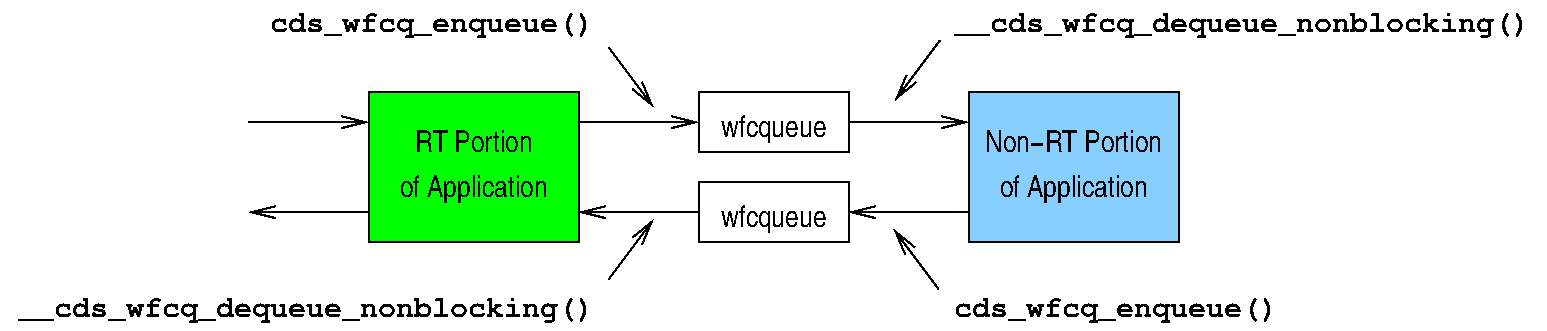
The absolute safest approach is to use a wfcqueue,
using non-blocking interfaces in both directions.
That way, if the non-real-time portion of the application is delayed,
at worst the real-time portion gets CDS_WFCQ_WOULDBLOCK.
Quick Quiz 1:
Is CDS_WFCQ_WOULDBLOCK really the worst that
can happen?
One way to allow the non-real-time portion of the application to use the blocking interfaces is to use multiple sets of queues and of non-real-time threads, as shown in the following figure:
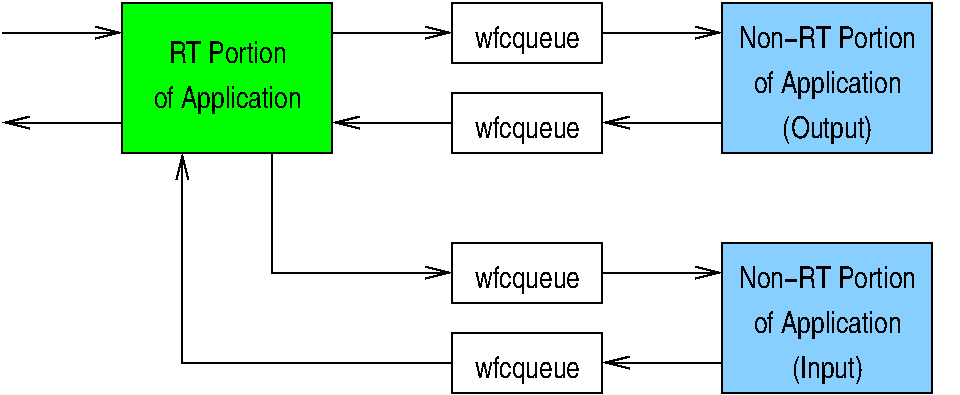
This arrangement allows the output thread to block waiting on messages because the input thread handles all the asynchronous events.
Quick Quiz 2: But then the real-time portion of the application must poll not onewfcqueue, but two! Doesn't that degrade its response time?Quick Quiz 3: Of course, the real-time portion of the application just periodically polls as part of its processing loop, but how do the non-real-time threads know when to attempt to dequeue?
Queues can be used for a number of other purposes, for example, as a deadlock-avoidance strategy: Instead of acquiring a lock out of order, enqueue a request that is later serviced by some other thread running in a clean environment. This strategy is used in the Linux kernel via mechanisms such as workqueues.
Answers to Quick Quizzes
Quick Quiz 1:
Is CDS_WFCQ_WOULDBLOCK really the worst that
can happen?
Answer: That depends. If the real-time portion of the application is periodically enqueueing messages without regard to whether or not the non-real-time portion of the application is consuming them, then, yes, eventually memory might be exhausted, which will of course result in memory allocation failures.
Let this be a lesson to you. If the non-real-time portion of the application is failing to respond, stop sending stuff to it!!!
Quick Quiz 2:
But then the real-time portion of the application must poll not one
wfcqueue, but two!
Doesn't that degrade its response time?
Answer: It might well do so. If this is a problem, another approach is to interpose a third non-real-time thread between the input and output threads and the real-time portion of the application. This third thread can multiplex and demultiplex messages to and from the real-time portion of the application, allowing the real-time portion to once again poll only one queue. Setting this up is left as an exercise for the reader.
Quick Quiz 3: Of course, the real-time portion of the application just periodically polls as part of its processing loop, but how do the non-real-time threads know when to attempt to dequeue?
Answer: The output thread can use a blocking dequeue, which moves the decision as to when to attempt to dequeue into the dequeue operation. The input thread can use any number of strategies, including periodic polling. If polling is undesirable, for example, due to energy-efficiency concerns, you can use explicit wake-ups, for example, using POSIX condition variables or futexes.