

LWN.net Weekly Edition for August 20, 2026
Welcome to the LWN.net Weekly Edition for August 20, 2026
This edition contains the following feature content:
- Debian weighs eight options in vote on LLM usage: after much discussion, Debian developers are voting on what position the project should take on the use of LLM-based tools.
- Representing Python paths using pathlib: Trey Hunner wants Python developers to stop representing filesystem paths as strings.
- Bootstrappable builds: how and why: building a modern Linux user space from a tiny seed.
- Fedora prepares for the end of AF_ALG: the upcoming Fedora 45 release will restrict use of the kernel's user-space interface (AF_ALG) to the Crypto API.
- 128-Bit page tables for Arm: a patch series to add support for 128-bit PTEs on Arm, just in case 72PB of RAM is not enough.
- BPF, continuous testing, and stable kernels: an update on the status of the BPF testing infrastructure.
- Development statistics for the 7.2 kernel: a look at one of the busiest development cycles in kernel history.
This week's edition also includes these inner pages:
- Brief items: Brief news items from throughout the community.
- Announcements: Newsletters, conferences, security updates, patches, and more.
Please enjoy this week's edition, and, as always, thank you for supporting LWN.net.
Debian weighs eight options in vote on LLM usage
The Debian Project is voting on the usage of large language models (LLMs) to make contributions to the project. The first proposal, sent in late July by Matthias Geiger, would expressly forbid any contributions to Debian that are created by or with the assistance of LLMs. That kicked off a firestorm of discussion and a flood of alternate proposals. Debian developers are now voting on eight proposals in total that range from banning LLM-assisted contributions to explicitly approving them, as well as the standard "none of the above" option that would leave Debian with no agreed policy.
Debian and AI
While other distributions, such as Fedora and Gentoo, have settled their policies regarding AI-assisted contributions, Debian has held off on making a decision—though not for a lack of discussion. The topic has come up several times over the years without any resolution.
In 2024, Tiago Bortoletto Vaz worried
that Debian was "already facing negative consequences
" due to the use of
AI-generated content and wanted to gather input from Debian developers ahead of
a possible general resolution (GR) on the topic. The discussion led him to conclude
that the project was "far from consensus on an official Debian position
"
regarding the use of generative AI, and he did not pursue a GR.
In February 2026, Lucas Nussbaum opened
another discussion on the topic by proposing that Debian allow AI-assisted
contributions. He said that
people who admit to using AI were being attacked by "a group of people that
vehemently rejects AI
", and he wanted to find a middle ground for Debian to
move forward. The resulting
discussion was, in his
words, "generally civilized and interesting
", and he thought that a
GR might not be needed after all.
It's time
Last month, Geiger decided that one is needed after all. He said that it is
"time for Debian to make a statement regarding generative AI and LLM
usage
". He opted to skip ahead to officially submitting his GR proposal,
rather than testing the waters as others had done, because the topic had already
been discussed in detail. Once the dam broke, a flood of proposals followed. In
total, there are eight proposals for Debian's developers to consider, summarized
below, plus "none of the above".
- No LLM contributions to Debian via Social Contract. Geiger's option: it would amend Debian's Social Contract to expressly forbid any contributions to Debian created with the use of LLMs or other generative-AI tools. It does not apply to upstream projects that use LLMs or AI-related software (thus, packaging an application for AI-related development would be unaffected).
- Allow
AI-assisted contributions with conditions. Nussbaum's option: it expressly
allows AI-assisted contributions as long as the contributor follows a set of
conditions, including assuming full responsibility for technical merit,
security, license compliance, etc. It also requests, but does not require,
disclosure if "
a significant portion of a contribution is generated or substantially assisted by a tool
". The form of disclosure is left to the contributor. - Reject LLMs as
far as practical, update code of conduct. Proposed by Ian Jackson, this
option would amend Debian's
code of conduct to forbid the use of LLMs to create "
messages to humans
" such as bug reports, emails, discussions on Salsa, and even blog posts aggregated on Planet Debian. It requests that contributors "avoid the use of LLMs in their Debian work
", but concedes that a complete ban on LLM output is impractical. - Accept AI contributions for Debian-specific work. This option, proposed by Pierre-Elliott Bécue, expressly allows contributions created with or by generative-AI tools, with a set of conditions placing responsibility on the submitter.
- Responsible
use of generative AI. Under Marc Haber's option, Debian would issue a statement
describing its position as neither endorsing or prohibiting the use of
generative-AI tools in Debian, and says that use of such tools "
is neither exempt from nor subject to special rules beyond the standards already expected of Debian contributors
". - A cautious
approach to generative AI. Proposed by Tobias Frost: if adopted, the
project would issue a statement describing its position on generative AI as
encouraging contributors to "
avoid the use of generative AI where practical and to prefer human authorship, collaboration, and technical understanding over AI-generated output
". However, it does not forbid the use of generative AI, and affirms that the project trusts its developers to uphold Debian's "high quality values
". - Debian is
created by humans. This proposal, put forward by Gard Spreemann, was
inspired by the GCC project's
AI policy and the rust-lang/rust
policy from the Rust language team. It disallows output of generative-AI
tools as direct contributions, but allows contributors to use such tools
"
as an [assistive] tool to explore, research, analyze, critique, etc.
" - Avoid the use
of LLM: climate destruction is a deal breaker. Holger Levsen's option
would have Debian issue a position statement against LLMs on environmental grounds as
well as "
significant ethical, legal, technical, and social concerns
". However, it acknowledges LLM usage can be "hard if not impossible to detect
". Therefore, it is a position statement only: there would be no prohibition of LLM usage for Debian contributions.
Debian uses the Condorcet method for voting to find the majority-preferred option, so voters will rank their choices in order of preference rather than needing to choose only one. Because Geiger's option would modify the Social Contract it requires a three-to-one majority to pass.
Discussion
It is difficult these days, if not impossible, to participate in open-source
projects without being immersed in the debates about LLM usage. The positions
and arguments deployed in Debian's discussion will likely be familiar to most
readers. For example, regarding code copyright, Geiger argued that there is
"huge uncertainty
" about the copyright status of LLM outputs. He failed
to see how LLM-generated code could comply with the Debian Free Software
Guidelines (DFSG): "If you let a function be generated where you can't be
100% if you don't have any license obligations due to the training
data
".
Others were not persuaded that LLMs posed a risk to Debian or violated the
DFSG. Russ Allbery pointed out
that many of Debian's upstream projects, including the kernel, "have decided
that none of these concerns matter and they're going to ignore all licensing
issues around LLM output
". The ship had sailed, he said. Ted Ts'o said that he was
"perfectly happy to certify that I believe there is no copyright
issue
". He argued there was no more copyright uncertainty around LLM output
than humans who might write code after searching for examples on Stack Overflow.
Simon Richter said
that he expected the US legal system would decide that LLM outputs were
"unrelated to training data and not copyrightable
". However, he reached
that conclusion not based on its legal merits, but because "the expensive
lawyers
" would be working against a finding that LLM output was not
distributable due to copyright problems.
The topic of quality, or lack thereof, was also explored at length. Bécue's first draft of a ballot option, which became "Accept AI contributions for Debian-specific work", originally included specific prohibitions against using an AI assistant to push commits or upload packages. Nussbaum complained that this added arbitrary restrictions against personal workflows. He asked what the problem was with asking a local agent to commit and push to a branch.
In the ensuing back-and-forth, Bécue said that he used
LLMs daily, but believed that "the more automated and fast-paced a
tool is, the more safety nets are required
". He was not arguing that
humans don't do low-quality work, but he wanted to prevent automated systems
pushing a higher volume of it. Haber responded
that people should be able to use LLMs to do low-quality work if they were going
to do so anyway:
But why should we not let us be assisted in doing crap if we're going to do crap anyway? Bad people are going to do AI assisted crap, good people are going to produce less crap if they are allowed to use assistance of their choice.
Bécue said that would
lead to producing "10 times the crap 10 times faster, which has a significant
impact and produces more strain
" on the project. In another message, he said that most of
the people he knew using generative AI "read less than half the code it
writes
" and warned that they were already having difficulty in trying to
write code on their own.
Matthias Urlichs, however, did not share Bécue's concerns about quality. He said that his own packaging had improved a lot since he started letting an LLM do it, and he doubted that Debian would see 100 times more crap:
Conversely, I can immediately think of a couple of use cases where LLMs would add some tangible value. Like, chasing down reproducible-build failures. Or filter [Intent to Package bugs] for existing software that already does what the new package wants to add. Or help scan packages in the NEW queue. Or help keep our clones of Rust, Go, Python and/or Node packages up to date – which frankly is one of the more tedious and un-rewarding jobs in Debian.
Compilers and calculators
Ts'o commented
on the concerns about people who depend on LLMs forgetting how to code. He
acknowledged that calculators led to a decline in the number of people who could
do math in their heads, and that compilers had definitely led to fewer people
who were good at writing assembly language. "But I think it's more about
people being less proficient at certain skills that are no longer as important,
and less about some more general claim about 'cognitive decline'.
"
Adrian Bunk brought up the
debhelper
tool for building Debian packages as an example closer to home for Debian. He
said that there was now a clear lack of knowledge among Debian developers about the
internals of building Debian packages, which meant that they were "often lost
how to debug and fix issues in their packages
". Bunk and Ts'o submitted
these examples of skill loss as arguments for, not against, the use of LLMs.
However, Bécue remained unconvinced. He replied to Ts'o that
his calculator comparison "has some merit, but is not a good one
anyway
". He worried that people would turn to LLMs without having first
developed their ability to think critically about the problems, which left them
"both vulnerable to a rug pull, but also to be fed garbage without ever
realizing it
".
Environmental impact
The environmental impact of LLMs was a dominant theme in the discussion. Bas
Wijnen said
he could not understand how others could agree that LLMs "destroy our
ecosystem
" but conclude that it is not a deal-breaker when considering their
use. The only response he had seen on that point was that "other activities
are also bad (some even worse) for the climate
", which he did not see as a
reasonable argument.
All of our users live on this planet, so protecting that planet is a matter of life and death for them. In other words, caring about something as big as climate change during our Debian work is not (as was suggested elsewhere in the discussion) a violation of the social contract. On the contrary, I would argue that the social contract requires us to care about climate change and prevent it as much as we can.
Nussbaum replied
that he was not dismissing the topic of climate change, but claimed that
singling out LLMs "sounds like AI-bashing, not like a well-reasoned
discussion about the impact on climate change
". He said that Debian could
reduce its environmental impact in other ways, such as building fewer packages,
stopping large-scale QA efforts that require many rebuilds, and suggested ways
Debian could reduce its "travel-induced CO2
" by changing how DebConf is
organized. "Why would Debian encourage me to travel to India, South Korea,
Argentina or Japan for Debconf, but at the same time, decide that it is
unacceptable to use AI assistance
"?
In a postscript to a message about
free-as-in beer LLMs, Ts'o suggested that the concerns about environmental
impact were merely "an excuse to justify a position that someone has already
has made for other reasons
". Didier 'OdyX' Raboud responded that
Ts'o's type of argument was "either ill-advised, or in bad faith
". His
concern was not with ecological impact on a per-query basis, but with the effect
of the LLM industry overall:
AI companies are not a mandatory feature of our societies. We don't have to allow AI companies to destroy books to train LLMs [0]. We don't have to allow building datacenters to put strain on local electricity or water networks, or increase the local temperature. In a summer with massive drought and fires burning through Europe and North America, with (public) funding desperately missing in firefighting, climate action, etc, deciding to invest 30 B€ in AI Gigafactories [1] _is_ a choice that we "as a species" are making, and one that I don't think is right at all.
It is unclear whether the dozens of messages exchanged between Debian developers have used more, or less, energy than asking an LLM for help building a package; it is, however, clear that few, if any, minds were changed during the discussion.
Vote
Debian has dealt with divisive decisions before, of course. For instance, the project struggled with the question of choosing a default init system for some time before it was decided by the Debian Technical Committee in February 2014; The topic reared its head again as a GR in October 2014, the outcome of which was that a GR was not required.
The init debate—in the form of "init-system diversity" was rekindled in 2018, and voted on as a GR at the end of 2019. Ultimately, Debian chose systemd with support for exploring other alternatives. While the init debates brought out strong feelings, and words, it does not seem to have dealt great harm to Debian in the long run.
Considering the number of options, and the fact that several are similar in nature, it is difficult to guess which of the proposals is likely to win. If history is any guide, though, the likely outcome is that the project will dust itself off and get back to work after the vote—though the topic may well bubble up again before all is said and done.
The voting period began on August 15, and will run through August 28. While there were quite a few people participating in the discussion, there were far fewer developers who weighed in than likely voters; according to the tally sheet for the vote, more than 130 developers have cast their ballot already out of more than 1,000 eligible voters.
Whatever option wins, one hopes that the project is better for it in the long run.
Representing Python paths using pathlib
At the outset of his PyCon US 2026 talk, Trey Hunner said that his goal was for attendees to stop representing filesystem paths as strings and to use pathlib instead. That's kind of a tall order, at least for longtime Python users, since string-based paths have been pervasive—and mostly work. It is that "mostly" part that makes Hunner want to see things change, of course, so he set out to describe a lesser-known corner of the language and to try to change some minds.
Hunner introduced himself as a Python trainer for development
teams; he also runs Python
Morsels, which is a "weekly skill-building service
" for
developers of all skill levels. Beyond that, he publishes a newsletter with a
weekly Python tip.
Strings and paths
For most of Python's history, paths have been represented as regular strings, which works and will continue working forever, but there are problems with doing so. Over ten years ago, Python 3.4 introduced pathlib based on PEP 428 ("The pathlib module – object-oriented filesystem paths") in order to clean things up. There are multiple problems he would be describing for string paths: the standard-library alternatives to pathlib are difficult to find and awkward to use, while string paths can lead to bugs and distinguishing paths from other strings can be hard to do.
He turned the clock back to 2016, when many users were still on Python 2.7,
to look at what existed in the standard library to work with file paths. There
were four modules, os, os.path,
glob,
and shutil,
"that we might have reached for
" to deal with paths.
shutil has "a bunch of high-level file-related stuff, including
seven different functions for copying files and directories
". By
comparison, glob is simpler, with just glob() and
iglob() for doing shell-like pattern matching for path names.
os.path is used for "manipulating file paths
", including
splitting, joining, and querying them.
The story with the os module is more complicated, he said. In his opinion, Python has two "junk drawers" in its standard library: os and sys. os is for things related to the computer and operating system, while sys contains "junk" related to the Python interpreter itself. os has lots of functions for working with paths and files, as well as many that are for other purposes. He briefly listed off more than a dozen file- or path-related functions, but then showed seven slides listing all of the other functions in os—probably around 200 in all (slides, use arrow keys to advance). His point was that it was not easy to find path functions in os, not to mention the others scattered in os.path, glob, and shutil.
But, if paths are just strings, he asked, why can't the string-manipulation functions be used instead of those in os.path? He showed three versions of some code for a Django project that set a variable to the path of the file directory's sibling templates directory. The first:
    BASE_DIR = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
    TEMPLATES_DIR = os.path.join(BASE_DIR, "templates")
and the second:
    BASE_DIR = os.path.abspath(__file__).rsplit("/", maxsplit=2)[0]
    TEMPLATES_DIR = BASE_DIR  + "/templates"
Both need to have imported os.path, naturally. The second works,
but is somewhat less readable perhaps; it also suffers from a portability
problem, in that Windows uses "\" as its path separator, so it may
not work on that kind of path.
Importing os allows using os.sep, but even that is not
all that readable, he said:
    BASE_DIR = os.path.abspath(__file__).rsplit(os.sep, maxsplit=2)[0]
    TEMPLATES_DIR = BASE_DIR  + os.sep + "templates"
The readability and maintainability of the latter two examples is why the
utility functions in
os.path were added, he said. Meanwhile, depending on where various
parts of the path came from, there may be a mixture of forward and backward
slashes in it, which actually works on Windows, but looks pretty strange,
he said. (It does not, however, work at all on Linux.)
There is another problem with paths as strings, which is something Hunner calls "stringly typed code". Data that is passed as strings, when a better type exists is stringly typed. He gave an example (which apparently was from last year):
    target = "2025-09-25"

    if target[:4] == "2025":
        print("That's this year")
That works, but it assumes that the string is actually a date in the proper
format.
Using a datetime
object instead leads to a little more code but provides a guarantee that
the string is actually a valid date; otherwise strptime()
would raise ValueError:
    from datetime import datetime

    user_input = "2025-09-25"
    target = datetime.strptime(user_input, "%Y-%m-%d").date()

    if target.year == 2025:
        print("That's this year")
Hunner argued that using strings to represent paths is stringly typed as well. Returning to his earlier example, he showed how a Path object can change that:
    from pathlib import Path

    BASE_DIR = Path(__file__).resolve().parent.parent
    TEMPLATES_DIR = BASE_DIR / "templates"
As Hunner described later in the talk, the resolve()
method turns a Path into an absolute path and the parent
attribute resolves to the path of the parent directory. The slash
("/") operator is used to join two paths.
For code that uses type annotations, a Path object provides another benefit: a type checker can spot problems where strings and paths are being confused in the code. Being able to distinguish those uses makes it easier to reason about the code and to catch bugs in it as well.
Meanwhile, the Path version is easier to read than the os.path version he showed earlier:
    BASE_DIR = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
    TEMPLATES_DIR = os.path.join(BASE_DIR, "templates")
In order to understand that first line, he has to read it from right to
left, getting the absolute path of the file using abspath(),
its parent directory (dirname()),
and the parent of that. It uses nested calls, while the Path
version chains calls and attributes in a way that reads much more
naturally, at least to him.
He showed some examples where Path alternatives are easier to read and use, including replacing the classic with block for reading a file with a one-liner:
    with open("config.txt", mode="rt") as file:
        content = file.read()

    # one line replacement using Path
    content = Path("config.txt").read_text()
Making a directory using the os module means either using mkdir()
or makedirs()
depending on whether the intermediate directories should be created. For a
Path object, the mkdir()
method has a parents flag that can be used to create intermediate
directories. Likewise, for copying files, the Path object has
the copy()
and copy_into()
methods that were added in Python 3.14; prior to that, four separate
functions from shutil could have been used (copyfile(),
copy(),
copy2(),
or copytree()). "I can't tell which of these you need because I don't remember which one does which."
Using pathlib
The pathlib module contains one main thing, Hunner said: the Path object. The Path() constructor takes a string representation of a path and returns a Path object, which will either be a PosixPath or a WindowsPath depending on the underlying operating system. Those two types support all of the same operations and just differ in the way they normalize paths; users should not have to care.
There are a little over two dozen useful methods that can be called on Path objects, six attributes (e.g. name), and two class methods (Path.cwd() for the current working directory and Path.home() for a user's home directory). There are more than 70 attributes and methods, overall, but he only rarely uses the others.
When pathlib was first introduced, users often needed to convert
Path objects to strings in order to use them
(e.g. open(str(path), ...), but over time more and more of
the Python builtins and standard-library modules have added support.
"Pretty much every utility in Python that accepts a file path will also
accept a Path object
", he said. He listed six separate
examples and noted that even functions and methods that are explicitly
designed to take path strings will also work with Path objects.
So, legacy code that still uses the older functions
(e.g. os.path.join() or os.mkdir()) will still work
correctly when passed a Path object. Beyond that, most
third-party packages, such as Django, pandas, and pytest, will accept
Path objects. If a third-party package does not accept
Path objects, it is probably a bug that should be reported, Hunner
said.
The way to start using pathlib is to simply start passing the strings that specify paths to the Path() constructor:
    >>> from pathlib import Path
    >>> notes_path = Path("Documents/notes.txt")
For portability, the forward slash should be used to separate names in
string literals, but a WindowsPath will normalize any
backslash-separated names as needed.
A Path object can be used to do various things, such as joining it to a file name. That can be done with the joinpath() method or by using the slash operator:
    >>> from pathlib import Path
    >>> home = Path.home()
    >>> path1 = home.joinpath(".config.toml")
    >>> path2 = home / ".config.toml"
The slash operator looked odd to him when he first saw it, but it has grown
on him and he now finds it pretty readable. In addition, the constructor
accepts multiple arguments (either strings or other Path objects)
and joins them together, so:
    >>> path3 = Path(home, ".config.toml")
    >>> path3
    PosixPath('/home/trey/.config.toml')
    >>> path1 == path2 == path3
    True
All three mechanisms are equivalent and none is clearly better than the
others, but he said that the third approach is typically only used when it
is not known whether the components are strings or Path objects.
Hunner said that he finds the os.path functions to be
"unfortunately named
", with squished-together, often shortened
words, while the equivalents in pathlib are better thought-out.
For example, he prefers path.name over using
os.path.basename(path) and the same goes for path.parent
over os.path.dirname(path). Even more compelling is using
path.suffix over os.path.splitext(path)[1]. He noted
that there are cheat sheets for pathlib in an article that he
wrote and in
the Python
pathlib documentation.
Inheriting and extending
Since Python 3.12, classes can extend the functionality of pathlib.Path via inheritance. So, for example, a custom Path class could be created that has a method to change directories:
    import os
    import pathlib

    class BetterPath(pathlib.Path):
        def chdir(self):
            os.chdir(self)
Inheriting from Path is not likely to be common, but when it is done,
any attributes used by the new class, perhaps for storing metadata, can be propagated to derivative
Path objects (e.g. parent) by overriding the with_segments()
method in the subclass.
Back in 2016, PEP 519 ("Adding a file system path protocol") was accepted for inclusion into Python 3.6. It described what was needed for an object to be considered "path-like", so it would be accepted anywhere a path string or Path object was expected. Effectively, it explained what kind of quack was needed in order for duck typing to determine that the duck should be treated as a path. It turns out that a class only needs to implement a single method, __fspath__(), which returns a string or bytes representation of the path-like object, in order to quack correctly.
Path-like objects that follow the path protocol will be accepted by
open() and other builtins and standard-library functions. In
addition, PEP 519 enables third-party path libraries. He thinks that
pathlib is great, "but if you don't like it, there's a whole
ecosystem of path-like objects beyond just pathlib
". He
showed a "very silly example
" of a path-like class, which did not
inherit from Path, that worked with open() and would work
anywhere else where a Path can be passed.
Common mistakes
Next he described some of the mistakes that new Path users make.
The first is something of a historical accident. When the feature was
introduced in Python 3.4, the usual way to open a file using a path was the
open()
method for Path. When Python 3.6 was released with PEP 519,
there was no need to use that method because the open() builtin started
accepting path-like objects. Since it is simply historical at this point, he thinks that the open() method for
Path should be avoided; "not everyone agrees with that advice,
but I'm on the stage so I get to say this
", Hunner said to laughter.
Another common mistake is to convert Path objects to strings unnecessarily. For displaying or logging a path, using an f-string implicitly converts the object to a string:
    >>> print(f"Reading: {path}")
    Reading: example.txt
There is no need to do an explicit string conversion of the object for
open() or any of the other functions that accept path-like
objects. "If you think that you need to convert a path to a string, you probably don't."
Lastly, the flexibility of the Path() constructor means that multiple strings can be joined into a single path by passing them to the constructor. There is no need to create a Path object for one piece and use joinpath() or the slash operator to construct the final path.
There is a persistent, but he thinks mostly
unwarranted, complaint: pathlib is slow. "It is true that
pathlib can be slower for some operations, but readability is
sometimes worth a small performance penalty.
" He compared the
performance of os.walk()
with Path.walk()
on 400,000 files. The two were roughly the same at just under one second
(0.91s for os.walk() versus 0.85s), but he noted that
Path.walk() returns strings rather than Path objects.
Converting those strings to Path objects made the test take 2.22s.
Most path operations are not done in tight loops, so the penalty of that
may not really matter much, he said. Path objects provide more
readability, which is also important. "Optimize only when it really matters.
"
He concluded by noting that pathlib is not simply a different API,
it is, instead, an acknowledgment that file paths are "important enough
to warrant their own data type
". It is meant to make handling path
operations easy by representing them properly in the language.
[I would like to thank the Linux Foundation, LWN's travel sponsor, for its assistance with my trip to Long Beach, CA for PyCon US.]
Bootstrappable builds: how and why
This year's edition of the Free and Open Source Software Yearly conference, better known as "FOSSY", moved north to the beautiful (and enormous) campus of the University of British Columbia (UBC) in Vancouver, Canada from its home for the three previous editions: Portland, Oregon, in the US. There were many different types of talks at FOSSY, from deeply technical kernel-track topics, through talks on legal and community issues, to the "FOSS in Daily Life" talks. In the "Toolchains and Other Development Tools" track, Timothy Sample gave a presentation about bootstrappable builds, which is somewhat less well-known than its cousin, reproducible builds, though LWN did look at the topic just over two years ago. In short, a bootstrappable build is one that starts with a tiny program that can build another slightly larger program, which can build yet another, and so on, until the entirety of a modern Linux user space is built from a small seed. Ultimately, it results in code with a completely understood origin—unlike a typical Linux user space today.
He began by asking attendees whether they had heard of bootstrappable builds
and whether they were generally familiar with the idea; he seemed impressed
that the majority knew the term and that roughly half of the audience knew
more than that. He said that he embarked on the path toward
bootstrappable builds almost ten years ago when he started using GNU Guix (which he pronounced
"geeks"—surprising me). At that time, if you
were using Guix, you were contributing to it, he said with a chuckle. Guix is a
"functional package
manager
" that is similar to (and inspired by) Nix.
For both Guix and Nix, all of the software in the system is represented in
a "derivation graph
", which describes how to build each of its
programs. There are various inputs required in order to be able to build a
particular program, which are specified in the graph. The way to build
each of the inputs (and, of course, the inputs to the inputs and so on) is
also represented in the graph. "There's hundreds and hundreds of nodes
in modern software, which is terrifyingly complex.
"
He gave the example of a Python program. It, obviously, requires Python in
order to run, but Python is a C program, so a C compiler is needed.
That C compiler is written in some language, so a compiler for that
language will be needed. And so on. Guix collects all of that into the
graph, which is an object that can be looked at and explored. "So you
start wondering who compiles my compiler's compiler compiler and where does
it stop?
"
For a system like Debian, it stops at a C compiler binary that someone has uploaded to the repositories. For Guix, the original stopping point was a 250MB statically linked blob of GNU user-space programs. The answer to where all of that code came from is not entirely clear, of course, which was unsatisfying to Guix developers. That blob could be built reproducibly, which is good, Sample said, but does not solve the entire problem.
Bootstrappable
The basic idea behind bootstrappable builds is to create a system that can
be built without relying on pre-built artifacts. "Can we go from zero
to the modern day without having to just assume the existence of these
already-built-for-us artifacts?
" The classic recipe for yogurt
requires some yogurt to start the process, which is like how we normally
build a C compiler today—we start with an existing C compiler binary. You
might think about making sourdough bread with your grandmother's starter
brought over from the old country; "we're basically making C compilers
with Dennis Ritchie's starter carried over from Bell Labs
".
It is not just C, of course, as it is true for most languages. It is
something of a point of pride for languages to "self host" by writing the
compiler and other tools in the language itself. It is natural for the
language developers to do that, because
obviously their language is the best, but it leaves something of a
chicken-and-egg problem behind. Bootstrappable builds is an effort to move
beyond that and to build these tools "from scratch
".
Reproducible builds allow people to "have more confidence that the
binary you are using, which is actually executing on the computer,
corresponds to the source code
". A user can receive a binary that
purports to come from a set of source code files, but how can they be sure
that it does? With a reproducible build, they can create the binary
themselves and check to ensure that it is bit-for-bit the same as what they
were given.
Bootstrappable builds do exactly the same thing, but they handle a different failure mode. If a reproducible build fails to verify, that's because the person who built the binary is lying or mistaken about where it came from. Bootstrappable builds can prevent the kinds of problems that Ken Thompson described in his famous Turing Award lecture: Reflections on Trusting Trust.
An example that Thompson gave in that lecture asked where in a C compiler you can find the definition of "\n", Sample said. Looking in the source code of the compiler will not show a definition, it will simply provide the circular definition that "\n" is "\n"; the conversion of "\n" to ASCII ten is embodied in the C compiler binary itself. Thompson continued his lecture by noting that something rather more dangerous, such as a backdoor for the login program, could also be hidden in the compiler in the same way.
It is not just C compilers, or even just compilers, that can have this sort
of flaw; any self-hosting program can potentially fall prey to it.
Programs of this sort can remove details from the source code and have them
persist in binary form. As he was preparing for the talk, a colleague
pointed him at a recent paper ("Trusting-Trust Attack against an Entire Linux Distribution
through Binary Manipulation") that showed an actual attack of this sort.
The researchers inserted a backdoor into the strip
program on NixOS, which is run on nearly every binary that is built on the
system. "They were able to backdoor basically every single program on
the system in a way that's completely invisible from source-code
analysis.
" That is the kind of attack that bootstrappable builds is meant
to thwart.
While the security angle is the largest benefit of bootstrappable builds, Sample said that there are software-freedom aspects too. Being able to read the source code is useful, but knowing that the source code corresponds to the running program is important as well. There is also a sense of pride that many programmers have in making their code clear and understandable. Ensuring that the code can be inspected and that all of its details exist in some available body of source code is part of that.
The best way to handle bootstrapping is proactively, he said. Before a
compiler is self-hosted, it is normally written in some other language;
preserving that code and maintaining it alongside the self-hosted version
provides a means to ensure that nothing is hidden in the binary. That is
what the GNU Guile
project does; it is a version of Scheme that is used by Guix and various
other projects. Guile still has a C implementation of the language
available to use for bootstrapping the compiler. GNU Make has a makefile, of
course, but it also has a shell script in case no make is
available. "We recognize that we're a fundamental build tool and that
there should be another on-ramp here.
"
For tools that only support a self-hosted build,
there are some techniques that he and others in the bootstrappable-builds
community use to circumvent that lack. The first is an "archaeological
dig
", which uses the history of the project to find a non-self-hosted
version; that version is built using the tools from that era. "Then
you move through history, version after version [...] until you get to the
modern tool.
" Sometimes some of
the version steps can be skipped, but overall it is a slow process.
"In some ways, it just sort of kicks the can down the road; technically, you
do have all of the source code
", but asking someone to look at, say, 12
different versions of a tool is rather daunting; it would be nice for there to
just be one version to verify.
An audience member asked if this was like using the OCaml version of the
Rust compiler to bootstrap to current Rust; Sample said that it was, except
that the OCaml Rust compiler is no longer available. Another attendee
noted that the Plan 9 C
compiler that was used to build the Go
programming language is still available, as is the earlier Plan 9 C
compiler that built that C compiler. Those kinds of build chains are
normal for Guix, Sample said. For Rust, it currently starts with the
C++-based mrustc
to build Rust version 1.54 or 1.56; modern Rust is 1.97 and nearly every
version in between must be built, which is quite slow. When rebuilding a
Guix system, Sample said, "it's very depressing when you hit this chain
of Rust compiles
"; an attendee said it took them three days to build
that on their Arm laptop.
The end result of those chains is not all that nice because of the number
of steps that need to be verified. An alternative is to "purpose-build
a new tool for bringing something up
", which is exactly what mrustc is.
The result is nicer, with a single code base to inspect, but "it takes
forever
" to develop a bespoke tool of that sort. He has done some of
that and the result is unsatisfying at some level because the tool simply
exists to enable another tool to be bootstrapped. Beyond that, the tool
will require maintenance to keep up with the target tool, but it is not
particularly exciting work that might attract other developers.
The most successful bootstrappable builds use a combination of the two approaches. As with Rust and mrustc, they go back in time to a simpler version that can be built with an alternative bespoke tool, then move forward to the present-day version. In fact, mrustc can now build Rust 1.90, but that has not been integrated into Guix yet; he plans to do so in the near future.
Projects
He returned to Guix and its seed, which is only around 256 bytes these
days, rather than the 250MB blob. It consists
of a program called hex0, which can "build up through many
many layers and eventually gets to GCC 2, GCC 4, and modern GCC, and modern
Guile and all these tools
". While that's "super cool
", there
are a lot of caveats; the biggest is that a statically linked Guile is
still used "to do a bunch of stuff
". That is "absolutely
cheating
", he said, but there are plans to fix that, which he is
working on, but it is going to take some time to achieve.
The other thing that often disappoints people is that there is no answer
for how to bootstrap the kernel. Guix assumes there is a kernel; "it'll bootstrap all of userland from nothing, but the kernel is outside
of the scope of this discussion
".
A related project is live-bootstrap,
which works with Guix and uses many of the same tools and approaches;
live-bootstrap moves more quickly than Guix, however, and has explored
bootstrapping kernels using the Fiwix kernel. Live-bootstrap regenerates any of the
machine-created files that might accompany a source release
(e.g. configure) as well; it is "very admirable how
thoroughgoing they are
", but the "downside is it's extremely
complicated
".
To demonstrate that, he put up the 182-step
process to bootstrap the system. It lists tools that need to be built
in the order needed to arrive at a base Linux system. It starts with
hex0, builds various different tools, including multiple C
compilers of increasing complexity, many versions of Perl in order to
bootstrap Automake and
Autoconf, and so on.
It does not include tools like Rust and Go; "it's just the modern
GNU/Linux base system
".
"It's great that they've done that work, it's pretty wild and
complicated, and it would be nice to improve that
", Sample said.
The hex0 program provides a way to turn a string of hexadecimal text into a binary with those bytes. Normally, that is used to build hex1 and hex2, which are also hexadecimal converters adding single-character labels (hex1) and more complete labels that allow fancier addressing modes (hex2). Using those, M0 can be built, which allows using assembly mnemonics, rather than hex opcodes.
Sample said that he had omitted a few steps but that eventually M2-Planet can be
built, which "is almost like C
"; code can be compiled, but
sometimes certain C features will be missing so it will need to be
rewritten to avoid them. At that point, everything switches over to use GNU Mes, which is a Scheme
interpreter written in the M2-Planet dialect of C. Mes has a C library
(Meslibc) and
a C compiler written in Scheme (MesCC). Those allow building the Tiny C Compiler (TCC), which "is a
simple C compiler but much more complete than MesCC
". Modern
development tools can then be built using TCC.
Germ
That is the path taken by both Guix and live-bootstrap. "It works, [...]
but everything is super complicated.
" He is working on a different
approach, called Germ
(or Germ Lisp), which is introduced in a
blog post on his site. In that post, he pointed out that the existing
mechanism goes from C to Scheme and back to C, all to end up in Guix, which
is Scheme-based. But, he recognized, that "a primitive Lisp interpreter is not much more complicated than a primitive assembler.
"
He works on Mes and likes it; "sometimes I get paid to work on Mes, Mes
is great
". But he is also writing a Mes replacement, which is not all
that uncommon. There are Mes replacements being written in Haskell and ML,
for example; everyone who looks at the problem immediately wants to write
the replacement in Forth, he
said. Bootstrapping Forth via a hex monitor is an obvious use of the
language, but most developers do not want write the rest of the code in
Forth, he thinks; "I would rather read the binary
". From the
audience, Keith Packard said: "Assembly is easier to write than
Forth.
"
Scheme folks are different, Sample said, and are willing to write code in
that language. The intent of Germ is jump over all of the intermediate
steps and have a Scheme interpreter from the start. "It just says:
'Scheme, go!', well it has two stages, but almost 'Scheme, go!'.
" It is
how Mes was designed originally, he said; it took some shortcuts that
allowed it to succeed early, "but now it's getting stuck
".
Germ is about 2.25KB; he wanted it to be 2KB, but missed that goal by a
little. It is a binary that "can run almost-Scheme
"; it is just enough
Scheme that it can run an assembler written in Scheme. That assembler is
used to build the second stage, which is "kind of just like a Scheme
interpreter
". It has contiguous bytes and vectors, features for I/O and working with the kernel, and it will almost run
unmodified Guix build scripts (there are still a few dangling items to
fully make
that work). It uses MesCC to compile C code and has a Scheme shell that he
wrote years ago for handling shell scripts; "eventually it'll run
awk scripts and sed scripts
".
Sample said that attendees might be expecting a demo at that point in his talk, but that he had been giving one throughout, as his slides were running on his laptop using Germ. He added an interface to SDL, provided a "draw pixel" function for Germ, and loaded in the font information. As was guessed by an audience member (winning the 1000-nerd-point prize), the font he used was from the original Symbolics Lisp machine.
He took a brief tour of the Germ code, showing the Scheme-based assembly
(like that in memory.scm),
while noting that he maintains a regular assembly version (memory.s)
in parallel. There is a practical side to that choice, as well, since
by using a real assembler "you get debugging symbols and everything,
with the other one you most certainly don't
", he said with a laugh.
Overall, Germ hits his goals well. It quickly rises to a high level of abstraction that exactly fits the Guix use case. All of the Guix build scripts are written in Scheme; Guix avoids using shell scripts for the most part.
It's conceptually simple. Now I know not everyone loves Lisp or Scheme—somehow it's controversial—but regular old, plain Scheme has got to be better than this tower of bespoke assemblers and compilers for languages that don't quite exist.
That statement was met with some laughter from the audience as might be
guessed—Lisp/Scheme are controversial and somewhat divisive, after all.
The biggest problem that Germ faces is not surprising, he said:
performance. He is writing a Scheme in the same way that the original Lisp
interpreters were written in the 1950s, using assembly language. "I
can't bring to bear all of the modern techniques because writing in
assembly is hard and keeping things small is hard.
"
Germ is "faster than Mes, technically
", at least on a
micro-benchmark of making function calls. But whenever a real program is
being run, Mes is much faster because nearly everything in Germ runs
in Scheme (e.g. loops). For a comparison, it takes about 100 seconds for
Mes to compile itself on his desktop, or 60 seconds if the experimental bytecode compiler
is used. Compiling Mes on Germ, with a bunch of optimizations that he is
testing enabled, takes around 140-150 seconds. The problem with that is
that Mes is "unbearably slow
", so being worse than Mes is something
of a non-starter.
In addition, Germ is less portable than Mes, which can run on Arm and
RISC-V, while Germ is x86_64-only at this point. Another problem Germ faces
is that "people just hate parens
", which is irrational, but he can
relate because he was one of the haters until he ran into Guix. Scheme
is a relatively easy language to implement, though, and, since it meshes well with
Guix, makes a lot of sense for bootstrapping.
Future
Looking ahead, he would like to integrate Germ with Guix "in a way
that's exciting for everyone
". Currently, Guix depends on
%bootstrap-guile, which is the statically linked Guile binary, but
Germ could potentially replace that; it could also be replaced with Mes,
but either way would be a nice step forward.
He would also like to work on the performance of Germ; moving some of the
looping constructs into the assembly code is some low-hanging fruit.
"That feels like band-aids
", however, and he wonders if he should
simply write a compiler; there is a need for a compiler backend for C, so
maybe the two could be combined. He has some starting work toward a RISC-V
port that he would like to finish as well.
He ended the talk there, but there was lively Q&A session after that. Packard asked how much of Scheme was implemented in Germ; was it R5RS compliant, for example? Sample said that it is a Guile Scheme, but does not have extras like the Guile Object Oriented Programming System (GOOPS); it is effectively an R7RS Scheme, but he took some shortcuts like removing floating-point numbers since he does not need them.
Mark Wielaard asked how many of the 182 steps were removed by this work.
Sample said that in his "dreaming mind
", Germ would serve as a wedge
that others would use to create Scheme-based shortcuts to remove some of
the long chains of builds (e.g. Perl and autoconf) and reduce the problem
further. He acknowledged Wielaard's estimate of more than 80 steps still
remaining; Wielaard pointed out that someone could sabotage step 73 and it
is likely that it would go unnoticed. Sample agreed that it was a known
flaw in the approach, but that the number of steps was being reduced to
slowly improve the ability to verify everything.
The seed could be smaller than the 2.25KB if he wanted, an attendee said.
He agreed and noted that he could simply use hex0 to load the
first stage of Germ, but "I don't want to play games, I want to actually
get
results
". He did not want to start any fights and respected those who
use hex0, but it feels a bit like cheating to him.
The final question was whether Germ had a read-eval-print loop (REPL); the
answer was yes, of course, since he had been displaying his slides using
it. He showed the REPL and his use of the (next-slide) and
(prev-slide) functions; he also demonstrated that it gives a
backtrace on errors. "I program in this all the time, it can't be
driving me crazy; it has to have a few creature comforts.
" He took
some shortcuts (e.g. no floating-point numbers), but it has some extras
too, such as delimited
continuations.
He closed by noting that Germ has "the fanciest macros
", including a
working syntax-case
form. He had to implement that himself, since, ironically, there is no
bootstrappable syntax-case—it is written using syntax-case.
[I would like to thank the Linux Foundation, LWN's travel sponsor, for helping with my travel expenses to Vancouver for FOSSY.]
Fedora prepares for the end of AF_ALG
The Linux kernel's user-space interface (AF_ALG) to the Crypto API has been linked to a number of recent high-profile security problems, including Copy Fail and successor vulnerabilities. It was deprecated earlier this year. Eric Biggers, and other kernel developers, have been working to remove it from the kernel. With that in mind, the Fedora Project is planning to restrict use of AF_ALG in the next Fedora release in the hopes of nudging remaining users of the API to prepare for its eventual removal.
Goodbye AF_ALG
Allowing user space programs to request crypto operations from the kernel was both popular and controversial when AF_ALG was added by crypto subsystem maintainer Herbert Xu in 2010. Xu designed AF_ALG to allow user-space programs access to hardware cryptographic accelerators in order to provide performance gains.
Some, however, were unconvinced that this was a good idea. Christoph Hellwig,
for example, said that it
was computationally intensive code that had "no business in kernel space
unless absolutely required (e.g. for kernel consumers)
". He added
that CPUs were gaining "proper instructions
" for cryptography, which made
providing a user-space API even less useful.
In hindsight, it turns out that adding AF_ALG was a bad idea—but not, necessarily, for the reasons that its critics expressed at the time. The reason that kernel developers are now working to get rid of AF_ALG is that it has proven to be not only unnecessary, but a regular source of kernel vulnerabilities as well, as Biggers pointed out in his patch documenting the deprecation of AF_ALG.
AF_ALG is almost completely unnecessary, and it exposes a massive attack surface that hasn't been standing up to modern vulnerability discovery tools. [...]
This isn't sustainable, especially as LLMs have accelerated the rate the vulnerabilities are coming in. The effort that is being put into this thing is vastly disproportional to the few programs that actually use it, and those programs would be better served by userspace code anyway.
The time has clearly come to rid the kernel of AF_ALG, but kernel developers have to be cautious about ripping it out to avoid disrupting user-space programs that have come to rely on it.
One of the popular user-space programs that makes use of AF_ALG is the cryptsetup utility, which is used to set up disk encryption, such as LUKS volumes, using dm-crypt. The project pointed out that AF_ALG had been deprecated in its release notes for cryptsetup 2.8.7.
The release notes state that cryptsetup would be able to
use a user-space crypto library in lieu of AF_ALG if it was not present, though
some methods would require root access. Users were warned that the absence of
AF_ALG "could cause severe compatibility issues if the required algorithm (or
encryption mode) is not implemented in the userspace library
". The Serpent and Twofish ciphers are
specifically mentioned as missing from several user-space libraries.
Christoph Anton Mitterer had spotted the warning when cryptosetup 2.8.7-rc1
was published. He raised
his hand on the linux-crypto mailing list, on July 8, to ask about
potential fallout from the deprecation of AF_ALG. Mitterer said that he did use
those ciphers and "it would really be quite unfortunate if sooner or later I
couldn't use them
". He asked if anything was being done to ensure that those
would remain available.
Biggers replied that
Mitterer might have gotten the wrong impression from the cryptsetup release
notes. The things that had been removed from AF_ALG so far, zero-copy and
async-execution support, should have no impact on cryptsetup. "There are
indeed more people turning off AF_ALG in their kernels now; however,
general-purpose distros aren't doing that.
" That statement was true in July,
but it will not be true much longer.
General purpose distributions are doing that
Justin Forbes and Peter Robinson put forward the "Disable in
Kernel Crypto Userspace API (Phase 1)" change proposal for Fedora 45, which was announced
by Aoife Moloney on July 22. The proposal notes that AF_ALG is deprecated
in the kernel "with some parts of it being actively removed early in the 7.2
cycle
" due to security risks. It recommends restricting AF_ALG's use in the
Fedora 45 release "so we can do a controlled ending of
support
". Change proposals are expected to identify the impact that a change
would have on the distribution—the proposal says that there are not many
Fedora packages that are known users of AF_ALG, "so the impact should be
minimal
".
The proposal does identify a few known users of AF_ALG in Fedora, however: cryptsetup, the iNet Wireless Daemon (iwd), and the Linux kernel crypto API user-space interface library (libkcapi), which is used by dracut. It says that those users are unaffected by the change, though there may be third-party packages that use AF_ALG. In that case, it makes sense to identify them now so that they can be modified before AF_ALG goes away entirely.
The first phase uses the upstream patches due to land shortly, likely in 7.3, to limit the use of the API to the known apps and restricts the use. This allows Fedora to identify unknown users and gracefully deal with them before the active demise of the interface upstream providing users a more graceful process rather than universally pulling the rug without any notice.
The upstream patch being referred to is not identified, but it seems to be the one posted by Biggers on June 22, and applied by Xu on July 5. Biggers added a sysctl knob, af_alg_restrict, with three possible settings for AF_ALG: a zero for unrestricted, one for limited functionality, or two for completely disabled.
Beginning with Linux 7.3 the default value will be set to 1: that will
enable a limited algorithm allowlist for unprivileged processes such as iwd,
bluez, and iproute2, and a longer one for privileged processes. He said that
"common use cases such as iwd and bluez [Bluetooth] are taken into account
already
", and he had verified that iwd still worked with the new default
setting.
The contingency plan for the Fedora change proposal is to re-enable AF_ALG before Fedora 45 is released if it is found to cause too many problems. The presumption is that Fedora users will not notice.
Discussion
During the discussion on the Fedora devel mailing list, Ondrej Kozina said that he did not understand why the change was needed, given that AF_ALG was already being removed from the kernel.
Robinson replied
that there were a few reasons for the change. One was to communicate the
coming removal of AF_ALG so that Fedora users were aware; the other was
to ensure that the breaking change was made on a release boundary rather than in
the middle of a release cycle, since Fedora 45 will ship with the 7.2 kernel
and then move to the 7.3 kernel once it is released. "We don't want the
upstream patches heading to 7.3 to suddenly break users [systems] mid-release
when upstream yanks whatever rug they choose whenever they choose. It doesn't
make for a good user experience does it?
"
That did not quite satisfy Kozina, who argued
against turning off AF_ALG without a replacement. He complained, for
example, that cryptsetup would require users to have CAP_SYS_ADMIN for use with
some of the ciphers, and that Fedora would have limited support for TrueCrypt and VeraCrypt
containers. Robinson pointed
out that many of the use cases identified by Kozina were not present in
Fedora itself. "I believe these would only be used if a user when out of
their way to use those, generally via a manual install process.
" He
reiterated that AF_ALG is going away "whether we like it or not
" and the
idea was to get Fedora users ready ahead of time.
Barry Scott said
that he had a LUKS 2 vault on a Raspberry Pi 4 he had configured
"with advice from the *internet*
" using a cipher that would be affected
by the AF_ALG restrictions. "Clearly I will have to migrate to a supported
cipher before upgrading to f45.
" Robinson observed
that "the internet wasn't entirely correct
", and said that Scott would
need to migrate to a different cipher "before long
", but not for
Fedora 45.
Ian McInerney wondered
what this meant for Fedora 44, which was released in
April. "Since this change is targeted at F45 and kernel 7.2, does this
mean that F44 will not get kernel 7.2 released to it and stay on kernel
7.1?
" Forbes replied
that he had a method for adding or removing patches for specific Fedora
releases, so Fedora 44 would still get 7.2 without the AF_ALG restriction
patch.
The Fedora Engineering Steering Committee (FESCo) discussed the change in a ticket and voted to approve the change with five in favor of the change, and no votes against. The beta release for Fedora 45 is scheduled for September 15. It will be interesting to see whether restricting AF_ALG causes many problems for Fedora users, or if its phase out will be relatively uneventful.
128-Bit page tables for Arm
The size of a processor's page-table entries directly limits how much physical memory that processor is able to access. Back in the 32-bit days, that limit was 4GB, an amount of memory that once seemed nearly infinite, but which would now struggle to hold a basic AI-enabled "hello world" app. The expansion to 64 bits on most popular architectures would seem to have removed those limits now; some Arm systems, for example, can use 56 of those bits to access up to 72PB of memory. So it might be surprising that the Arm architecture is evolving to support even larger page-table entries (PTEs). This patch set from Anshuman Khandual adds support for 128-bit PTEs, but who will benefit from this capability is not entirely clear.The information of most interest in a PTE is a physical address — the address of the actual memory for bottom-level entries, or the address of the next table for higher levels. Not all of the bits in the PTE hold that address, though; if nothing else, the lowest bits, which correspond to the offset within the page in a virtual address, can be used for other purposes. Our article "On pages and folios" describes PTE entries in some detail; this diagram, showing how a 64-bit PTE might be divided, is taken from that article:

On a modern, 64-bit Arm system configured for 56-bit addresses and 4096-byte pages, a maximum of 44 bits of the PTE can be used to represent the physical address of a page in memory, while 12 bits are available for housekeeping purposes.
Expanding a PTE to 128 bits obviously makes it possible to store more information in that entry, but at a cost: doubling the size of PTEs will, clearly, double the size of the page tables. For some workloads, page tables already occupy more memory than users would like; every page occupied by a page table is unavailable for use by the system's workloads. Since one page can only hold half as many PTEs as before, there are implications for huge pages; a 2MB PMD-level huge page on a 64-bit-PTE system drops to 1MB when PTEs grow to 128 bits, and PUD-level huge pages shrink from 1GB to 256MB — a factor of four, since there are two levels of page tables that are eliminated for those pages. The sizes of multi-size transparent huge pages that can be coalesced for faster translation lookaside buffer (TLB) access also drop by similar factors. For workloads that are heavily dependent on huge pages for performance, those reductions could prove painful.
Given that there are clear costs involved with going to larger PTE sizes, one would expect that there would be gains in other areas; otherwise, there would be little point in making the change. To understand those gains, it is worth looking more closely at the new format. The details of what 128-bit Arm PTEs look like can be seen on this page; the bottom-level PTE format looks like this:
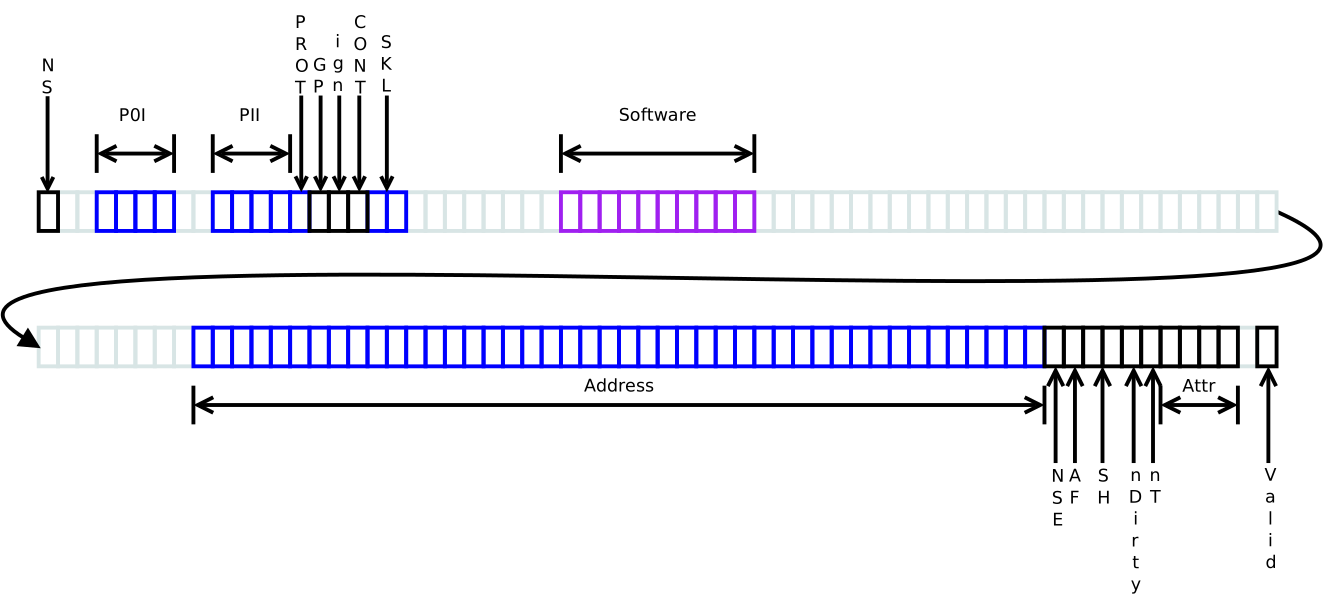
One thing that jumps out immediately is that the address portion of the PTE, stretching from bits 12 to 55, is only 44 bits in length. Add in the 12 offset bits, and the maximum address size is 56 bits, the same that is currently possible with 64-bit PTEs. So expanding the range of physical memory that can be addressed is not an immediate goal of this change. That said, it is worth noting all of the reserved bits — the bits shown in gray and without labels. There are 35 reserved bits above the most-significant address bit, leaving quite a bit of room for future expansion of the address field.
There are ten bits of the PTE that are not interpreted by the hardware at all; they are reserved for software use. That is double the five bits that are available on Arm systems with 64-bit PTEs. Five extra bits may not seem like a lot, but the kernel should eventually be able to make good use of them for memory management.
Bits 109 and 110 are the "skip level" (SKL) field. This field, which is present at all page-table levels, controls how the page-table-traversal process works. On most systems, the page-table hierarchy is rigid, with the expected number of levels (usually between three and five) always present. The one exception is for huge pages, where one or more levels are removed at the end of the search. Consider the PMD, which sits one level above the final page-table level; one entry in the PMD points to an entire page of PTEs, and covers (typically) 2MB of address space. By setting a bit in the PMD entry, though, the kernel can indicate that the entire 2MB has been assigned in a single page — a PMD-level huge page.
The SKL field generalizes this mechanism somewhat; it can indicate that the following step in the lookup process is a huge page, even if it is another level in the page-table hierarchy rather than the final step. That feature would appear to open the door to using huge pages for the page tables themselves, which would have the potential of speeding address translation and reducing TLB use.
The kernel changes required to support 128-bit PTEs are relatively small, consisting mostly of a set of macro definitions describing where the various fields and bits are. The most disruptive part has to do with page-table manipulation. When working through entries at various levels of the page-table hierarchy, it is important to read them atomically, so that the entire entry is coherent. That reading is done with READ_ONCE() in current kernels, but READ_ONCE() depends on atomic operations, and Arm CPUs do not have 128-bit atomic operations. Similar concerns apply to the modification of PTEs as well. The patch series wraps these accesses with a new pair of functions (ptval_get() and ptval_set()) that default to READ_ONCE() and WRITE_ONCE(), but which can be overridden by the architecture if need be. For Arm systems built for 128-bit PTEs, those functions are implemented with atomic ldp and stp (load-pair and set-pair) instructions.
In the current implementation, at least, the kernel must be specifically built for 128-bit PTEs, and kernels built that way will be unable to boot on CPUs that do not support that PTE size. That will make life harder for distributors; they have strong incentives to keep the number of kernels they build to a minimum. Fixing this problem will almost certainly involve a fair amount of boot-time code patching, but that may be required before distributors will consider enabling support for the larger PTEs.
This series has been through a few RFC iterations and appears to be stabilizing somewhat. Of course, relatively few people have hardware that supports 128-bit PTEs, so the amount of in-the-field testing of this work is necessarily limited. By the time that hardware becomes more widely available, though, Linux may well be ready to support it. But, in the short term, it is not at all clear that many systems will benefit from making use of this feature.
BPF, continuous testing, and stable kernels
Ihor Solodrai and Shung-Hsi Yu wrapped up the BPF track at the 2026 Linux Storage, Filesystem, Memory-Management, and BPF Summit with a pair of sessions related to testing. Solodrai spoke about what has changed for BPF's continuous-integration (CI) testing. Yu spoke about what may be needed to test BPF updates in stable kernels more thoroughly. The BPF subsystem's CI tests are in a good place, they said; even so, Solodrai and Yu have a handful of possible avenues toward enabling better test coverage in the future.
BPF CI
Since last year, Solodrai has made several improvements to the BPF-CI infrastructure, which he maintains. He particularly wanted to discuss LLM-powered reviews, additional test workflows, and some updates he has made to the test infrastructure. LLM review is something that Solodrai had been looking into before Sashiko showed that it could work. He ended up producing his own independent implementation of the idea. The BPF-CI infrastructure uses Chris Mason's review prompts, semantic search, the Lore mailing-list archives, and the kernel source tree to produce reviews about BPF changes. The reviews are triggered via GitHub actions — making a pull request to the GitHub mirror of the BPF tree will produce, a while later, a comment on it with a review from the LLM.
At first, Solodrai didn't know whether this sort of thing would be useful. It
turns out that "everyone is excited about AI reviews right now
", so it
does seem to be. Sashiko, with a dedicated development team rather than just
Solodrai, is a more powerful tool, so he's considering turning off the BPF-CI-LLM
reviews. He intends to keep them for now because they use a different LLM
provider (Anthropic, rather than Sashiko's use of Google) and so produce a
slightly different flavor of review. He has also been using LLMs to investigate
and report on flaky tests, so that he does not need to investigate all of the
failures himself.
The conventional test coverage has been expanded too. The user-space portions of the BPF self tests now run with address sanitization (ASAN) enabled. That was supposed to catch bugs in libbpf, but has mostly caught bugs in the tests themselves so far, which is still useful. Veristat, a tool in the kernel tree that measures how long it takes to load BPF programs, is now run on an expanded corpus of programs to catch performance regressions in the verifier.
Previously, the tests only ran against the BPF trees. Now, they also run against linux-next, which should help catch integration problems earlier. The self tests now run using both GCC and Clang. It used to be that they were compiled with both, but only the Clang-compiled tests were run. Now, the output of both compilers is run. That testing is still new and will possibly need more development, but Solodrai expects it to be useful.
The underlying CI-test infrastructure has seen some updates, mostly moving from Ubuntu to Debian, although some Ubuntu hosts remain. The test machines now use GCC 15.x and Clang 21.x, upgraded from GCC 14 and Clang 19. Solodrai wishes that the change in compiler versions was too trivial to mention, but it was a substantial amount of work. Soon, he hopes to upgrade to GCC 16 and Clang 22.
Alongside all of this good news, he does have some continuing complaints. Anthropic,
GitHub, the Ubuntu repositories, and even git.kernel.org are all prone to going
down. When he began working on CI infrastructure, failures were usually his
fault. Now, they're mostly the fault of the external services he depends on,
which is frustrating. "Software is less reliable these days — and I wonder
what the reason for that is — but if you have influence over any of these
companies, please make them more reliable.
"
He then asked the assembled developers what else should be tested in CI. Amery Hung had suggested to him having a dashboard that shows failures and successes by test case, instead of by build, he said. Everyone else was fairly happy with the state of the test infrastructure, although someone suggested that getting earlier access to the LLM-powered reviews would be nice.
That triggered a long discussion about the differences between the BPF-CI-LLM reviews and Sashiko. One advantage of the former is that it can search the mailing list archives for context; someone suggested bringing that idea to Sashiko developer Roman Gushchin. Even with that difference eliminated, the BPF developers still thought that having multiple independent reviews was helpful for catching subtle problems.
Stable kernels
Stable releases of the Linux kernel are put together using patches manually marked for backporting or picked up by the AUTOSEL patch-selection tool. The problem, Yu explained, is that AUTOSEL does not run the BPF self tests. When determining whether a patch ought to be backported, AUTOSEL checks whether it applies cleanly, but that is not enough to be sure that the verifier continues working as intended.
Last year, Yu proposed to fix this, and Solodrai helped by providing access to the existing self tests, so that Yu could duplicate the setup. Now, he has the self tests running against several different stable trees, and can share what the additional coverage has caught.
Most of the failures are noise, he said, especially from tests that are just wrong for the backported code. For example, just prior to the session he had sent a revert to back out a change that added a new test using a helper that wasn't present in the 6.6 kernel. Sometimes the failures are more subtle; one backported test set the network's maximum transfer unit to ten bytes, which is fine inside a network namespace, but on sufficiently old kernels it was affecting the root namespace, causing many downstream failures.
Build failures are more annoying, but are mostly a case of needing to backport additional patches that were missed. The testing has caught more complicated problems, too. It found a kernel panic caused by mistakenly assuming that a pointer in a struct_ops structure was valid, for example. Still, when Yu began this work he was hoping to catch more real regressions. The most useful way to make sure that regressions are caught is to backport the tests alongside any backported changes, he said.
Daniel Borkmann wanted to know how often Yu was running the tests. He answered that they run in the morning every day so that he can look at them when he wakes up. Borkmann asked whether there was a path to having the stable tests run as part of the main BPF-CI test suite. Yu didn't think that it was impossible, but he did note that he was doing things in a slightly different way — rather than running on every change, his tests just pull whatever is in the stable tree when they run. It's not as fast as watching the mailing list might be, he said, but it still usually lets him finish a complete test run before Greg Kroah-Hartman makes a stable release candidate. He does think that it's useful to have the stable testing separate from the main BPF-CI infrastructure.
Solodrai wanted to know how often Yu had to backport a test or examine a test failure on a stable branch. Yu is currently testing against three stable branches, and he sees something break about once a month. Not a huge amount, but it does need someone to maintain it, Yu said.
There is, of course, more to be done. More self tests should be backported, Yu said, and the testing should probably also include running on different architectures. It may even be possible to run the self tests from the BPF development tree on stable kernels, if a list of known-bad tests could be maintained. Either way, the kernel's BPF code is receiving more automated testing and scrutiny than ever. With so many exciting new features discussed throughout the summit, it's good to know that the tests are keeping pace.
Development statistics for the 7.2 kernel
Linus Torvalds released the 7.2 kernel on August 17, after noting that the number of fixes coming in was still "bigger than I would have wished for". In fact, 7.2 was one of the busiest development cycles in the kernel's history, adding nearly 600,000 lines of code. It's time to look at some statistics to get a handle on how the kernel's development community is changing.
There were 16,418 non-merge commits brought into the mainline for the 7.2 release, exceeding the (already busy) 7.1 release; it is, in fact, the second-busiest release in the kernel's history. Only the 6.7 release brought in more commits but, while 6.7 was dominated by the merging of the bcachefs development history, the volume for 7.2 is more broad-based.
These commits were contributed by 2,652 developers, a big increase over the previous record (2,479 in 7.1). If one looks at the history of developer involvement since the beginning of the Git era, the result is:
(This plot, like much of the information here, comes from the subscriber-only LWN Kernel Source Database). There has been a clear trend over that entire history: the number of developers contributing to each release increases over time. But the slope of that line has clearly changed.
The most active developers working on 7.2 were:
Most active 7.2 developers
By changesets Uwe Kleine-König 151 0.9% Rosen Penev 146 0.9% Ian Rogers 138 0.8% Johan Hovold 133 0.8% Arnaldo Carvalho de Melo 131 0.8% Chuck Lever 129 0.8% Eric Dumazet 121 0.7% Ville Syrjälä 115 0.7% Johannes Berg 112 0.7% Krzysztof Kozlowski 110 0.7% Thorsten Blum 108 0.7% Namjae Jeon 106 0.6% Christoph Hellwig 104 0.6% Sean Christopherson 100 0.6% Jakub Kicinski 96 0.6% SJ Park 94 0.6% Mike Rapoport 91 0.6% Dmitry Baryshkov 87 0.5% Eric Biggers 86 0.5% Rafael J. Wysocki 78 0.5%
By changed lines Matthew Stewart 83587 8.4% Hawking Zhang 62893 6.3% Miguel Ojeda 38979 3.9% Ian Rogers 31949 3.2% Darren Ye 20843 2.1% Ethan Nelson-Moore 16893 1.7% Harry Wentland 15233 1.5% Uwe Kleine-König 13803 1.4% Ingo Molnar 13649 1.4% Chuck Lever 10172 1.0% Eric Biggers 10067 1.0% Jakub Kicinski 9449 0.9% Rodrigo Siqueira 7749 0.8% Johannes Berg 7110 0.7% Arnd Bergmann 7085 0.7% Emil Tsalapatis 6810 0.7% Vivek Aknurwar 6544 0.7% Rob Clark 6490 0.6% Sabrina Dubroca 6401 0.6% Svyatoslav Ryhel 6072 0.6%
Uwe Kleine-König [KSDB] was the biggest contributor of commits to the 7.2 release with cleanups through the driver subsystem. Rosen Penev [KSDB] contributed a long list of LLM-authored bug fixes throughout the architecture-specific, driver, networking, and crypto subsystems, among others. Ian Rogers [KSDB] worked extensively on the user-space perf tool, as did Arnaldo Carvalho de Melo [KSDB]. Johan Hovold [KSDB] made numerous improvements, mostly in the SPI and USB subsystems.
Matthew Stewart [KSDB] reached the top of the lines-changed column by following the time-honored tradition of adding more massive, machine-generated amdgpu header files; Hawking Zhang [KSDB] did likewise. Miguel Ojeda [KSDB] brought the Rust zerocopy crate into the kernel source. Darren Ye [KSDB] added the MediaTek mt8196 sound driver.
Just over 8% of the commits in 7.2 carried Tested-by tags, while 48% included Reviewed-by tags. The review tags, in particular, are showing a mild downward trend in recent releases:
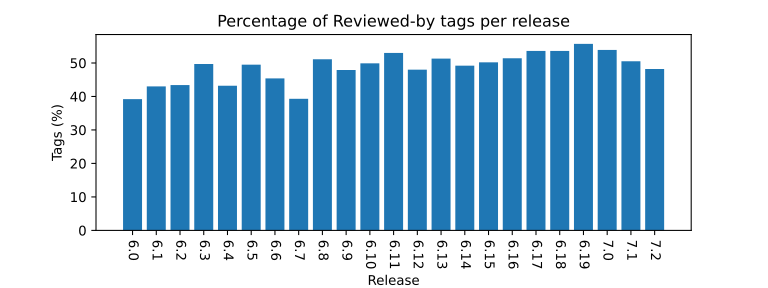
Whether that decline reflects an actual decrease in the amount of review taking place is unclear at best. In any case the most active testers and reviews for this cycle were:
Test and review credits in 7.2
Tested-by Dan Wheeler 117 7.0% Luiz Capitulino 54 3.2% James Clark 44 2.6% Sarthak Sharma 44 2.6% Venkat Rao Bagalkote 32 1.9% Tommaso Merciai 27 1.6% David Riley 27 1.6% Jie Gan 27 1.6% Geert Uytterhoeven 25 1.5% Arthur Kiyanovski 25 1.5% Marek Szyprowski 25 1.5% Randy Dunlap 24 1.4% Shivaprasad G Bhat 24 1.4% Rinitha S 21 1.3% Vitaly Prosyak 20 1.2%
Reviewed-by Konrad Dybcio 231 2.2% Dmitry Baryshkov 225 2.1% Andy Shevchenko 175 1.7% Geert Uytterhoeven 171 1.6% Krzysztof Kozlowski 152 1.5% Frank Li 147 1.4% Ilpo Järvinen 145 1.4% Christoph Hellwig 143 1.4% Jan Kara 121 1.2% Christian König 120 1.1% Linus Walleij 116 1.1% Alex Deucher 105 1.0% Simon Horman 102 1.0% Jeff Layton 101 1.0% Ido Schimmel 94 0.9%
Dan Wheeler [KSDB] is, as always, the top tester by virtue of his work with AMD graphics-driver patches. On the review side, Konrad Dybcio [KSDB] added his tag to 231 changes while Dmitry Baryshkov [KSDB] tagged 225; the same two, who both tend to focus on drivers and devicetree files for Qualcomm devices, were at the top of that list for the 7.1 cycle as well.
Work on the 7.2 kernel was supported by 249 employers that we were able to identify; the most active of those were:
Most active 7.2 employers
By changesets (Unknown) 2743 16.7% Intel 1512 9.2% 1191 7.3% Red Hat 873 5.3% AMD 813 5.0% Qualcomm 767 4.7% (None) 743 4.5% NVIDIA 535 3.3% Meta 441 2.7% (Consultant) 429 2.6% SUSE 358 2.2% Renesas Electronics 328 2.0% IBM 307 1.9% Kylin 278 1.7% NXP Semiconductors 264 1.6% Oracle 245 1.5% Arm 222 1.4% BayLibre 203 1.2% Microsoft 201 1.2% Bootlin 194 1.2%
By lines changed AMD 224121 22.4% (Unknown) 103861 10.4% 102565 10.3% Qualcomm 59021 5.9% Intel 53661 5.4% Red Hat 51559 5.2% Meta 38635 3.9% (None) 28218 2.8% NVIDIA 27417 2.7% MediaTek 22025 2.2% NXP Semiconductors 17692 1.8% BayLibre 15972 1.6% Oracle 12233 1.2% Microsoft 11786 1.2% Renesas Electronics 11103 1.1% Linaro 10209 1.0% (Consultant) 9362 0.9% IBM 9205 0.9% Texas Instruments 8398 0.8% SUSE 8350 0.8%
The most significant change this time around, arguably, is the significant increase in developers with unknown affiliation. This is partially, at least, a reflection of the ongoing flood of new developers entering the kernel community.
New developers and their tools
Each of the previous two kernel releases had set a record for the number of first-time developers contributing changes; 7.2 has broken that record again, with 613 contributors [KSDB] who had not been seen here before. Here, once again, the trend is clear:
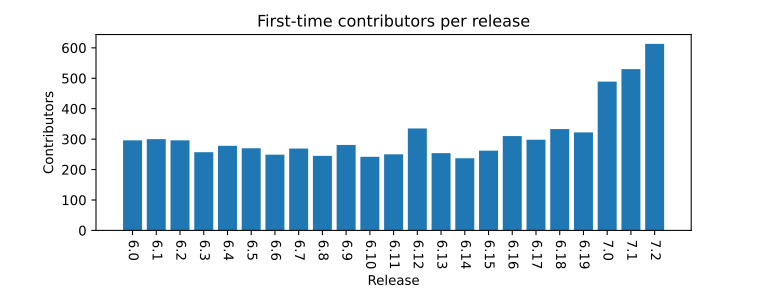
The most active new developer was Bryam Vargas [KSDB], who contributed 43 commits fixing problems in the input, NVMe, F2FS, AppArmor, Landlock, SELinux, NTFS, WiFi, ATA, SCSI, networking, Ceph, and Thunderbolt subsystems, among others. As has been observed here before, it would be difficult for a seasoned kernel developer to reach deeply into that many subsystems over the course of a single development cycle — at least, if they wanted to understand what they are doing. For a previously unknown developer to do this is surprising at best. Vargas's patches do not carry Assisted-by tags, though, so we are left to believe that this work was done without LLM assistance.
Overall, 1,111 changes in 7.2 (under 7% of the total) carried Assisted-by tags — a significant increase over the 301 seen in 7.1. The real count of LLM-assisted patches in 7.2 must surely be far higher than that, though. Many developers do not supply those tags (often — but not always — out of ignorance of the rules), maintainers rarely ask about LLM use, and at least one maintainer actively strips those tags when applying patches. Accurately tracking commits developed with LLM assistance may turn out not to be possible, but it sometimes feels like the kernel community does not care enough to really try.
The other way in which LLM usage is making itself felt in kernel development is in the area of patch review. There are 252 patches in 7.2 with Reported-by tags crediting the Sashiko review system [KSDB]; 568 commits mention Sashiko in their changelogs. Other LLMs are also clearly being used to find kernel bugs, though, with real effects.
The 7.2 release contains 4,830 commits with Fixes tags, indicating that they fix a bug introduced by a previous commit. To see just how significant an increase is, consider this plot, an updated version of one that has been seen here before (most recently for the 6.17 development cycle):
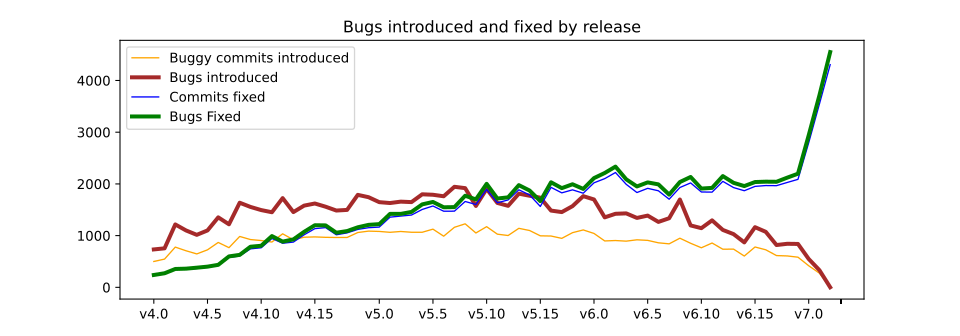
The heavy green line plots how many commits in each release contained Fixes tags, while the heavy brown line is the number of commits that were identified by Fixes tags in subsequent commits. The crossover point is at 5.9, suggesting that, as of that release, the kernel community started fixing more bugs than it introduced. That conclusion will not hold, though; it will take years for all of the post-5.9 bugs to be identified and fixed, and that line will shift as it happens.
The noteworthy part of the plot, though, is at the right-hand side, where the number of commits carrying Fixes tags increases dramatically, after having been roughly level for quite a few releases. That, it seems, is what happens once large numbers of people start turning LLMs toward the task of finding bugs in existing software. This is going to be an interesting trend to watch. The number of bugs cannot be infinite — even in the kernel — so the rate of bug detection and fixing must eventually fall off. The existing bugs will have been fixed, and LLM review will have reduced the number of new bugs introduced. At least, that is the hope.
If that drop-off does not happen, there will be some interesting questions to answer. It seems reasonably clear that the spread of LLMs has enabled people to create kernel patches who would not have been capable of doing so before. If that is true, it is not much of a stretch to conclude that, in many cases, the submitters of these patches do not fully understand what those patches do. Perhaps the LLMs are good enough that this understanding is no longer necessary, but it could also be that we are creating a pile of code that nobody has ever really understood, but which will need to be maintained in the coming years.
The Linux kernel is aimed at production use, not research or experimentation. But there is currently a massive experiment being run on the kernel's development processes and community. This community has absorbed new processes and tools many times over its 35-year history, and will almost certainly find a way to do that this time as well. But that absorption has not always been without turbulence along the way.
Meanwhile, there are nearly 14,000 non-merge changesets sitting in the linux-next repository and poised to be pulled for the 7.3 release; over 1,100 of them contain Assisted-by tags. It would seem that the high level of activity that has characterized recent releases will not be ending anytime soon. As always, keep an eye on LWN as we follow the next development cycle (and those that come after).
Page editor: Joe Brockmeier
Inside this week's LWN.net Weekly Edition
- Briefs: Brief news items from throughout the community.
- Announcements: Newsletters, conferences, security updates, patches, and more.