

LWN.net Weekly Edition for August 13, 2026
Welcome to the LWN.net Weekly Edition for August 13, 2026
This edition contains the following feature content:
- Bringing BPF to binfmt_misc: BPF programs may soon be able to manage interpreters for binfmt_misc.
- A look at CrossPoint e-reader firmware: open-source firmware for tiny ebook readers.
- KVM planes head for takeoff: an abstraction layer for managing multiple security domains within a single virtualized system.
- Even more formal verification for BPF: exploring the use of additional formal verification for application-specific constraints.
- Changes in shadow-utils password-expiration features: making periodic password rotation a thing of the past.
- Block-layer error injection: producing disk errors on demand to help with kernel-storage-code debugging.
This week's edition also includes these inner pages:
- Brief items: Brief news items from throughout the community.
- Announcements: Newsletters, conferences, security updates, patches, and more.
Please enjoy this week's edition, and, as always, thank you for supporting LWN.net.
Bringing BPF to binfmt_misc
The kernel is able to run a few types of executable files, including native binaries in the ELF format and interpreted programs that begin with the #! marker. It also, however, has a mechanism, called binfmt_misc, that can be configured from user space to enable the transparent execution of programs in just about any format. This feature has been relatively static for years, but it seems likely to receive some significant updates in the near future, including the ability to load BPF programs that can decide how to run a given program.binfmt_misc
In the beginning, Linux used the a.out format for binary executables. Support for the Executable and Linkable Format (ELF) was added to the 0.99.13 release in 1993, with distribution support (involving upgrades so painful that they still cause post-traumatic stress many years later) arriving around 1995. But, from the earliest days, there was interest in running programs in different formats as well. There were a number of Unix variants available for x86 systems, for example, each with its own binary format. There are languages, such as Java, that compile to their own virtual machines and need a separate interpreter. The kernel could gain support for all of these formats, but it was understood early on that a more general solution was called for.
That solution is binfmt_misc, which was added for the 2.1.43pre1 development release in 1997. In its current form, binfmt_misc presents a directory under /proc/sys/fs/binfmt_misc containing a file called register. Writing a string to that file registers a new format and tells the kernel how to recognize executables in that format; recognition can be based on a pattern in the first 256 bytes of the file itself, or on the file's name extension. For example, the documentation states that support for packed DOS applications can be had by writing this string to the register file:
:DEXE:M::\x0eDEX::/usr/bin/dosexec:
This line causes the kernel to recognized a packed DOS executable by the four-byte sequence \x0eDEX at the beginning of the file; it will invoke /usr/bin/dosexec to run that executable. As another example, any file with a .py extension and execute permission can be executed directly with:
:python:E::py::/usr/bin/python3:
After that has been done, .py files will be executed by the Python interpreter regardless of whether they contain a #! line. Multiple binfmt_misc entries can be made; the first matching entry is selected whenever an interpreter for a program must be found. In a delightful quirk, entries are checked in the opposite order that one might expect; the most recently added entries are checked first.
With binfmt_misc in place, the kernel developers allowed user space to set up whatever policy it needs for its own special executable formats; there was no longer a need to add dedicated support to the kernel for them. While this feature has seen a slow stream of improvements over the years, it has not seen many fundamental changes since its introduction nearly three decades ago.
Hermetic binaries
The formats defined with binfmt_misc all involve an interpreter that handles the actual execution of the program. Native binaries, instead, run directly on the CPU, but (unless they are statically linked) they still involve an interpreter; in that case, the interpreter is the dynamic linker, which is charged with loading the binary code into memory, loading libraries, and resolving references. The location of that interpreter is, for ELF files, found in the ELF binary itself, in the PT_INTERP segment; it is typically something like /lib64/ld-linux-x86-64.so.2. The kernel loads the interpreter, then lets it do the rest of the work in user space.
This scheme has worked well for many years, but there is always somebody who wants to do something different. Back in June, Farid Zakaria made the case that the Nix distribution needs relocatable binaries — binary programs that are fully self-contained (hermetic) and can run regardless of where they are placed in the filesystem hierarchy. A hermetic binary needs, among other things, a specific version of the dynamic linker, which may not be the default one installed on the system where the binary is expected to run. The PT_INTERP mechanism can allow for the specification of a different dynamic linker, but it requires an absolute path to that linker. That makes it hard to install the program (and its linker) in an arbitrary location without the need to patch the executable or engage in tricks with chroot() or namespaces. As a result, building this type of system is harder than it seems it should be.
Zakaria's proposed
solution to this problem was to allow PT_INTERP to specify a
path that is relative to the location where the executable is stored.
While the kernel community was supportive of end goal (running hermetic
binaries), this approach raised a lot of concerns. Kees Cook worried about security
problems resulting from manipulating paths in the kernel. Christian
Brauner was more
strongly negative, saying that Zakaria's approach was "ripe for
malicious loader injection attacks
" and that the problem should be
solved in a different way. Specifically, he thought,
the right approach was to augment binfmt_misc to allow the installation of
a BPF program to select the appropriate interpreter for a program.
BPF for binfmt_misc
Less than two weeks later, Brauner returned with a patch set implementing that functionality. At the time, he said that he intended to step away from the work at that point and let Zakaria finish the job. Zakaria duly responded with patches of his own a few days later. Brauner, showing how one truly rests while on vacation, continued to develop the idea himself in the meantime, though, returning on July 14 with an updated patch set that would appear to be the form the solution will take in the end.
There are two components to this work: the BPF interface, and additions to binfmt_misc. On the BPF side, there is a new struct_ops interface allowing programs to set themselves up to manage interpreters. A program registers a new operations structure with two callbacks:
    struct binfmt_misc_ops {
	bool (*match)(struct linux_binprm *bprm);
	int (*load)(struct linux_binprm *bprm);
	char name[BINFMT_MISC_OPS_NAME_MAX];
    };
The match() callback receives a pointer to a linux_binprm structure describing the program that is in the process of being launched; its job is to decide whether the BPF program is the correct one to manage the interpreter in this case. It serves the same function as the tests on specific bytes or a file extension does in the current binfmt_misc implementation. This program is sleepable, and it has the ability to read any part of the executable; unlike existing binfmt_misc tests, it is not limited to the first 256 bytes.
If the match() callback returns a true value, the load() callback will be invoked to select the interpreter that is to be used to run this program. There is a new kfunc, bpf_binprm_set_interp(), that is used to associate the interpreter with the program. If match() has returned true, load() must succeed, or the running of the program will fail.
The name field is used to identify this program when configuring binfmt_misc. That configuration is done by writing a string like:
:name:B::::bpf-handler-name:
to the register file. Here, name is the name by which the binfmt_misc entry is known (there will be a subdirectory created under /proc/sys/fs/binfmt_misc with that name), while bpf-handler-name is the name used when registering the BPF program. Once that registration is complete, the identified BPF program will be invoked whenever the kernel is trying to figure out how to run an executable program.
This functionality, it seems, is sufficient to satisfy the Nix use case; Zakaria put up a satisfied blog post that includes an example of the sort of simple BPF program needed to make relocatable binaries work. He pointed out that this feature can also be used to make the interpreter specified in #! lines relocatable, solving the problem for the script case as well.
Further steps
One might think that, with a seemingly satisfactory solution, Brauner would go back to his vacation with more enjoyment than before, but that was not to be. Zakaria had pointed out one little problem with the new binfmt_misc: the interpreter becomes the program that is run, while the program the user thought they were running ends up being an argument passed to the interpreter. It is the same effect that one sees with scripts on current systems; a tool like ps will show the interpreter as the running program rather than the script. Having ps or top show a system full of processes all running the dynamic linker might just lead to a complaint or two from users.
Brauner's answer to that was a 21-part patch series adding more binfmt_misc features. One of these is a new "transparent dispatch" mode that can be requested with either a flag (T) in the binfmt_misc entry or specified by the matched BPF program. When this mode is selected, the kernel behaves as if it were executing the binary directly, but substitutes the interpreter behind the scenes. The argument vector ("argv") and task command string remain as originally passed to execve(). The interpreter will receive an open file descriptor (specified in the AT_EXECFD auxiliary vector entry) that it can use to load and run the program in whatever special way it requires.
There is also a simpler mode that can be selected when the program to run is actually a native binary on the target system. In that case, the "loader substitution" mode, selected with the L flag, simply causes the interpreter returned from the BPF program to override whatever PT_INTERP was stored in the executable. So, in cases where the only thing that the BPF program must do is figure out where the dynamic linker is to be found (such as in the Nix case), the loader substitution mode is all that is needed.
Using either mode solves the problem that Zakaria pointed out, causing the executed program to show up under its own name rather than that of the interpreter.
The story is still not done, though. A BPF program has control over the path name for the interpreter that should run a given program, but it has no say over how that path name will be resolved. That resolution will happen in the namespace where the program was invoked. That can lead to problems if somebody with privileges in that namespace can, by mounting new filesystems, direct the resolution toward a special "interpreter" of their own. This problem is especially acute in cases where setuid programs are being run. Giving a potential attacker the ability to supply their own interpreter does not seem like a path toward pleasing results.
For normal binfmt_misc entries, where the interpreter is specified in the entry itself, the kernel can be instructed to open the file containing the interpreter and use it for every subsequent invocation. That ensures that the intended interpreter is always used, regardless of the environment in which a program is run. This feature was added in 2016 as a way of making interpreters available inside containers that are otherwise isolated from the host's filesystem.
A BPF program, though, can set the interpreter path to anything it wants, making it hard for the kernel to open any specific interpreter ahead of time. Brauner, naturally, has a patch series for that problem too. It allows the binfmt_misc configuration to include a set of known interpreters that will be opened by the kernel at configuration time; a BPF program can then choose between them whenever a specific program is to be run.
There were a couple of difficulties to overcome to enable this mode, though. In current kernels, a binfmt_misc entry must be fully specified with a single write to the register file; that entry becomes globally visible immediately after the write completes, so it cannot be left in a half-specified state. There is also a length limit on lines written to register that might constrain the number of interpreters that can be specified, especially if their path names are long. The solution to both problems was to create a new "disabled" mode allowing a binfmt_misc entry to be created without it becoming immediately active; multiple lines can then be used to adjust that entry before enabling it. An example of its use is given in the cover letter:
    cd /proc/sys/fs/binfmt_misc
    echo ':qemu:B::::qemu_user:D' > register
    echo '+aarch64 /usr/bin/qemu-aarch64' > qemu
    echo '+arm /usr/bin/qemu-arm' > qemu
    echo 1 > qemu
This sequence starts by creating a new entry, called qemu, that will invoke a BPF program named qemu_user; this entry will be represented by a file (also named qemu) in the control directory. The D at the end of the first echo command indicates that the entry is to be initially disabled. The following two lines add two interpreter choices, named aarch64 and arm, each with its own program that will be held open by the kernel. The echo 1 at the end enables the entry.
When the BPF program's load() callback runs on a matched program, it no longer needs to provide the full path to the interpreter; instead, it just gives the name of one of the preconfigured interpreters. The program will then be run with the given interpreter, again using the same file regardless of which namespace the program was invoked in.
As a final (so far) step, Brauner tossed in a short series setting up a knob to restrict how many interpreter files a given user can hold open. Without that limit, a hostile user running in a user namespace might be able to open enough "interpreter" files to starve the system of resources.
With the exception of the final resource-limiting series, all of this work is currently in linux-next, so it can be expected to land in the mainline during the 7.3 merge window. There is some documentation of the new features in Documentation/admin-guide/binfmt_misc.rst for the curious. The kernel's ability to transparently invoke binaries in exotic formats is about to become much more flexible; some people will, beyond doubt, do interesting things with it.
A look at CrossPoint e-reader firmware
There are a number of small, inexpensive, low-powered e-reader or e-paper devices that have promise as ebook readers with one minor problem: the firmware they ship with does not realize their full potential. To solve that problem, the CrossPoint Reader project looks to provide replacement firmware that offers necessary features, better performance, and a more pleasant reading experience. On August 7, the project released version 1.5.0, which opens large EPUBs more quickly, provides offline dictionary lookups, and has reworked settings for changing layout and font options. The release also improves support for right-to-left text as well as Chinese, Japanese, and Korean (CJK) text rendering.
Tiny e-readers
Mainstream e-readers, such as the Kindle and Kobo devices, have large, high-resolution screens with crisp fonts, lots of features, and are reasonably fast even when reading large ebooks. But they can be somewhat expensive, come tethered to proprietary services, and are too large to comfortably stash in one's pants pocket.
Last year, a Chinese company called Xteink started shipping pocket-sized e-readers globally. The first device was the Xteink 4, which uses an ESP32-based system-on-chip (SoC). It weighs less than three ounces (77g), has a 4.3-inch (114mm) screen with 480x800 resolution (no backlight) at 220PPI, and has physical buttons rather than a touchscreen.
Xteink is not the only vendor shipping tiny e-readers, there are several available with similar specifications, though it did seem to spark the most interest. The big tradeoff for these devices is their resource constraints—they have slow CPUs, only a few hundred kilobytes of RAM, and the display resolution means that fonts are never going to look as good as they do on the larger e-readers. Some of that can be overcome with the right firmware, though. Soon after the Xteink 4 went global, Dave Allie released the first version of CrossPoint to try to get more out of its limited hardware.
Since the first release, CrossPoint has grown well beyond a one-person show. There are more than 200 contributors to the MIT-licensed project, which now supports six tiny e-reader devices, based on the ESP32-C3 or ESP32-S3 chipsets, from a variety of vendors. All of the devices supported by CrossPoint are relatively cheap—one is as little as $50, and most are less than $80. The project aims for a monthly release cadence but missed with 1.5, which came out about six weeks after 1.4.0. 1.5.0 was also the first release with support for an ESP32-S3 device, the reTerminal Sticky "family notes display" device. Adding a new hardware target probably required a bit more testing than usual.
It is worth noting that CrossPoint does allow use of large-language-model (LLM) tools for contributions, since that's an important consideration for some users. However, the project asks that contributors disclose use of such tools in pull requests. It does not, however, accept features (LLM-assisted or not) outside of the narrow scope of providing a good reading experience.
The project's vision
and scope document explains that CrossPoint's goal is to focus on
"lightweight, high-performance firmware that maximizes the
potential of ESP32-based e-reader hardware, prioritizing legibility,
performance, and usability
". Features that, for example, improve EPUB
rendering, ebook library management, or provide optimizations for rendering on the
devices' eInk screens are
welcome. On the other hand, the project does
not want RSS readers, PDF rendering, writing tools, or other interactive
applications because such features are too resource intensive and
likely to drain the battery far faster than simply displaying an EPUB.
CrossPoint in a flash
I purchased the Xteink 4 in June, with the plan to use it as shipped, and install CrossPoint if the default firmware was unsatisfactory. The Xteink uses an SD card for storage, rather than built-in storage. Its battery is supposed to last for up to two weeks of reading; I can't verify that, but it's certainly good for several days of heavy use without a charge. The default firmware supports EPUB, Mobipocket, plain-text files, PDFs, as well as PNG and JPEG images.
The default firmware for the Xteink 4 is not terrible, but it does leave a bit to be desired. For example, its rendering of EPUB books was both slow and not very attractive. I found the navigation to be a bit clunky; the buttons are unlabeled, and sorting out which button was "Confirm" versus "Back", etc., was mildly frustrating. There is also little ability to tweak font settings, or justification.
The firmware is functional enough to get the job done, but it's not particularly pleasing while reading. After reading a few chapters of an ebook with the Xteink's standard firmware, I was ready to make the switch. However, in fairness, it should be noted that Xteink continues to update its stock firmware to add more features and enhancements. It's possible that, at some point, it will catch up to or even surpass what CrossPoint is providing.
The recommended method for installing CrossPoint is to use the web-based flash tool while the device is connected via USB-C—but some Xteink devices have USB flashing disabled. If that's the case, it's still possible to install CrossPoint by flashing new firmware from the SD card. In either case, flashing the CrossPoint firmware onto a device is not difficult and only takes a few minutes.
Managing CrossPoint
The first order of business is to get some reading material copied over to the reader. Devices with locked firmware may not allow connecting to the reader's storage over USB; and some of the devices supported by CrossPoint, such as the Xtenink 3, do not have a USB-C connector at all. So, copying files over USB-C may not be possible in many cases.
One way is to take out the reader's SD card, connect it to a computer, and copy files over; the simpler way is to copy files to the device over WiFi. Xteink's default firmware only lets users connect to a hotspot running on the device; the user has to disconnect from their current WiFi network and connect to the device's to copy files.
CrossPoint, on the other hand, has a built-in web server for file transfer and device configuration. CrossPoint devices can connect to a local 2.4GHz WiFi network and acquire an IP address using DHCP. Users can then reach the device by visiting "crosspoint.local" in their browser, or by using the IP address assigned by DHCP. Note that CrossPoint does not set up a secure connection; everything is served over HTTP, so it might be a bad idea to connect the device to public WiFi. If there is no local network available, CrossPoint also supports setting up a hotspot to connect to the device directly.
The web-based interface (shown below) allows users to upload files, create directories, rename or delete files, and so forth. When uploading EPUBs, it offers to optimize them for the device. It also lets users manage all of the device settings from the web interface, which tends to be a lot more convenient than thumbing through the settings interfaces on the device. Users can change the button assignments, modify display settings, adjust user-interface settings, change the CrossPoint theme, customize the book layout, font choices, and more. The User Guide has a good overview of the various settings that are available and should be up-to-date with the most recent release of CrossPoint.
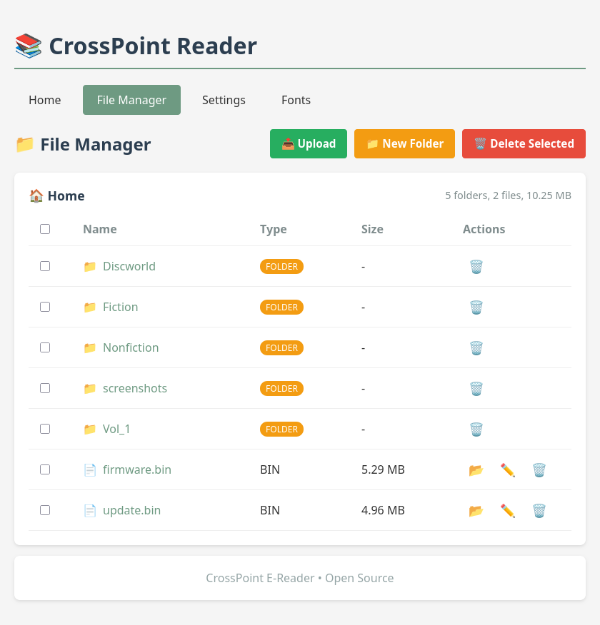
A few features are missing from the web interface, such as font downloads: CrossPoint's firmware includes two fonts, but there are a number of additional fonts that can be downloaded from the Reader Settings menu on the device, but not via the web menus.
If none of the fonts provided by CrossPoint prove satisfying, it is possible to upload custom fonts with a bit of extra work. CrossPoint uses its own font format, cpfont, rather than the BIN format used by Xteink. It does not support OpenType or TrueType formats directly, but the project provides a web-based font builder that can convert those formats into cpfont. Users can then copy the files onto the device through the web manager or just by copying the files to the SD card.
There is a CrossPoint plugin for Calibre for users who manage their ebook library with Calibre. It not only manages copying ebooks to the reader; it can also optimize EPUBs for devices running CrossPoint to help reduce memory usage. The plugin's optimizer converts images in the EPUB to a size more appropriate for small screens, removes embedded fonts, and may split large chapters to reduce their memory footprint.
Reading
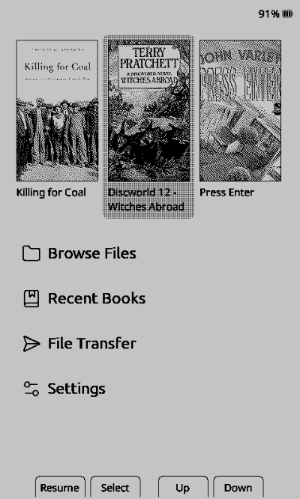
The CrossPoint reading experience is best described as "adequate", it handles novels and non-fiction content well, but technical content suffers a bit. For instance, when reading an LWN article as an EPUB on the device, it does not display text styled as code any differently than the rest of the content. Subheadings blend in with regular text as well; and, of course, all links are stripped out since it does not have any form of web browser.
Those minor complaints aside, though, reading non-fiction history, science-fiction, and fantasy novels on the device has been pleasant enough that I am quickly absorbed in the reading material rather than thinking about the specifics of the reader. It even has one feature I don't recall seeing on the Kobo or Kindle: auto page turn. Users can configure the reader to turn pages automatically at up to 12 pages per minute. This can be useful for hands-free reading—just place the e-reader on a table while holding a coffee and doughnut, perhaps—or just to save wear and tear on the buttons.
CrossPoint has support for looking up words in a dictionary, but users have to bring their own in the StarDict format. Happily, the project includes some suggestions on where to find such a dictionary in their documentation. Dictionaries for any of CrossPoint's supported languages should work, though there does not seem to be much documentation on installing dictionaries in multiple languages currently.
The firmware does have support for synchronizing reading progress with other readers, if they support KOReader's protocol. The project provides a free synchronization service with open registration, or users can set up their own server. It also has support for the Hardcover book-tracking service.
The project has a guide for setting up a CrossPoint development environment for those who would like to contribute or just modify their own firmware.
CrossPoint's roadmap is
split into three phases. Phase zero was about finishing the work in
progress before the project decided to be more disciplined about the
way it was working; according to the roadmap page, that phase is now complete.
Phase 1 is focused on expanding support to new ESP32-based
devices, reducing memory usage, and cleanup. It's unclear how long
this phase will last; the project's issue
tracker does not have tags or labels for phases or specific
releases. Phase 2's goal is to "make reading great in every
language
", with user-interface translations, better font support,
more themes, and so forth.
The project has come a long way in a short time, and new ESP32-based e-readers seem to be popping up all the time. It will be interesting to see how CrossPoint evolves and what new devices it supports, especially since the project and devices are not constrained by the need to keep users in a vendor's walled garden.
KVM planes head for takeoff
Virtualization places a guest system into a separate security domain, typically with fewer privileges than software running directly on the host. Increasingly, there is interest in creating multiple security domains within a single virtualized system as well. CPU vendors (and software vendors too) are implementing solutions; each of which, of course, is different from all of the others. KVM planes, currently under development by Jörg Rödel, Paolo Bonzini, and others in the KVM community, is an attempt to provide an abstraction layer that makes all of these features available on Linux systems; it is not a small task.When an operating-system kernel launches within a virtual machine, it typically has full access to all aspects of that machine. Interest in confidential computing, though, is driving efforts to split up that access. So, for example, a virtual machine may have a smaller kernel within it that is charged with implementing a trusted platform module (TPM) in software; if the virtual machine as a whole can manipulate that TPM, its results cannot be trusted. But if the TPM has its own range of memory that only it can access (and which might be encrypted to strengthen that protection) and its CPU state cannot be changed from the containing VM, then it should be secure — until somebody inevitably figures out a way to break that security, of course.
Many processor families have features meant to support this sort of secure enclave. Arm CPUs can provide Realm Planes, which have varying levels of privilege regarding memory protections, exception handling, and more. AMD's SEV-SNP secure-virtualization feature can support up to four virtual machine privilege levels with similar sorts of controls, and Intel's TDX implements partitions. Microsoft's Hyper-V hypervisor has the concept of Virtual Trust Levels, which supports a secure kernel and "trustlets" that carry out security-related operations. In the end, each of these features works toward the same goal, and systems developers would naturally prefer to not have to worry about the details of the specific CPU their code is running on today.
The proposed answer to this need is KVM planes, the patches for which were last posted by Rödel
in June. According to this documentation
patch, the "planes" name was chosen this way: "Ah, and because x86
has three names for it and Arm has one, choose the Arm name for all
architectures to avoid bikeshedding and to displease everyone---including
the KVM/arm64 folks, probably
". This posting derives from an earlier
implementation posted by Bonzini in 2025.
A plane encapsulates a privilege level implemented by the processor or hypervisor; one plane would represent an SEV-SNP virtual machine privilege level, a TDX partition, a Hyper-V virtual trust level or, yes, an Arm Realm Plane. All planes share the same address space and many processor resources, but have their own copies of the CPU register set and some other resources. Switching between planes (to allow a lower-privileged plane to request a service from a more-privileged one) is handled with calls back into the hypervisor. Each plane is represented by an integer ID, with no defined relationship between IDs and relative privilege level.
A virtual machine, at creation, will have a single plane, running in the most privileged mode. There is a new KVM ioctl() (KVM_CREATE_PLANE) to create a new plane; it returns a file descriptor that can be used to control that plane. Virtual CPUs are contained within planes, so each created plane must have at least one virtual CPU added to it for it to be useful. The virtual CPUs contained within a plane must be a subset of those configured for any more-privileged planes.
A plane at a given privilege level can generally set the rules for planes with lower privilege. A plane cannot, however, grant any privileges (such as access to a specific range of memory) that it does not possess itself. Certain privileges, such as the ability to control the injection and handling of interrupts, may be restricted to the most-privileged plane.
For any given virtual CPU, only one plane can be executing at any given
time. The policy built into the posted patch set is that, if more than one
plane is runnable, the lowest-numbered of them is run. That is a somewhat
interesting choice, since the above-linked documentation patch states
clearly that "KVM is currently agnostic to whether low ids are more or
less privileged
"; arguably, the natural expectation is that the most
privileged plane would run first. Bonzini questioned
this decision, which had changed from previous versions of the patch set.
He also suggested that there would be value in making it possible for the
scheduling decision to be made in user space, "though that may not be
very important in the grand scheme of things
". There are many details
in this proposal that are likely to change as the requirements come into
better focus; the decision of which plane to run may well be one of them.
The patch set includes support for AMD's SEV-SNP privilege levels. It works with the Coconut secure VM service module to install that module at virtual machine privilege level zero, and a Linux system running in privilege level two. There is also a separate patch set from Sriram Nambakam using planes with the Hyper-V virtual trust levels, running the secure kernel at trust level one, and the guest kernel at trust level zero:
The RFC demonstrates loading and starting the secure kernel, communication between VTL0 and VTL1, and hypervisor-enforced kernel integrity (HEKI). The secure plane can protect VTL0 memory independently of VTL0, seal kernel text and read-only data, participate in module validation and permission changes, and validate kexec images.
The patches are intended to show how planes can be made to work with Hyper-V. Unfortunately, they are mercilessly undocumented, to the point of lacking even changelogs on most of the individual patches, making review somewhat more difficult. Some of the ideas behind HEKI in particular, which is aimed at having the privileged plane ensure the integrity of the unprivileged plane, can be seen in this (unmerged) 2023 patch series from Mickaël Salaün. (Nambakam posted a new version of these patches, with better changelogs, just as this article was being published. The work has been split into multiple parts, with one series adding host-side support and another with guest support).
The planes concept has been explored with a few patch postings at this point, along with discussions at a number of gatherings at community conferences. The KVM community is clearly trying to come up with an abstraction that can handle the features produced by CPU vendors in a general way. Chances are that this abstraction will have to evolve for a while yet before it is considered ready to set into stone, but considerable progress has been made to get it to this point.
Even more formal verification for BPF
BPF offers useful safety guarantees, but Kumar Kartikeya Dwivedi wants BPF programs to be even safer. At the 2026 Linux Storage, Filesystem, Memory-Management, and BPF Summit, he led a session (slides) discussing the possibility of adding domain-specific invariants to BPF programs. It was not a discussion intended to lead to the implementation of any particular kernel feature, but rather an overview of why additional formal verification might be needed, and how it could work with the existing BPF ecosystem.
The BPF verifier ensures that BPF programs cannot violate kernel invariants. They cannot acquire locks in the wrong context, call kernel functions with arguments of the incorrect type, etc. Individual places in the kernel that make use of BPF programs can impose additional requirements. For example, sched_ext has a watchdog that will kick out a BPF program that does not schedule a runnable task within a certain amount of time. All of this is necessary, but not sufficient, Dwivedi said.
Ensuring that the kernel does not crash is only part of ensuring that an entire Linux system remains usable, he said. BPF programs can still interfere with user-space operations in several ways, which impacts the practical safety of BPF programs, even if the kernel itself always remains available.
At Meta, where Dwivedi works, there are one or two cases every month where the sched_ext watchdog kicks out a scheduler. Usually, this is due to a small corner case affecting a specific combination of hardware and workload that the developers simply didn't anticipate. Worse, some cases cause a performance regression without failing outright, which is harder to detect and diagnose. Many scheduling bugs also occur only under low load, which makes them hard to test for before deployment. He shared a slide (number 6) showing the throughput of a server becoming worse under low load with a prospective scheduler change. That particular bug was caught, but only because an engineer noticed it while experimenting.
Another example of the same problem is BPF programs implementing express data path (XDP) load balancing. If one of those programs started dropping network traffic, the server could become remotely inaccessible. That isn't an insurmountable obstacle — a daemon can be set up to listen for a heartbeat and kick the XDP programs out of the kernel if network access is cut off — but it's an additional check that is needed for practical safety.
In both of these cases, there are additional domain-specific constraints that are checked at run time. They are not theoretically impossible to verify statically. Scheduler programs could potentially be proven to never leave a CPU idle with runnable tasks available. XDP programs could potentially be proven to always route every packet to some destination. But those kinds of verification are currently out of reach, and not something that the verifier can simply provide. Also, sometimes developers want to deliberately subvert those guarantees. Dwivedi didn't give a specific example, but concurrency-fuzz-scheduler, which is used to expose concurrency bugs by scheduling tasks badly, comes to mind. Which properties of a BPF program are important to correctness can be context-dependent.
BPF programs control system resources, and so we need
to have more confidence in them, even without static analysis,
lest bugs have a serious impact, Dwivedi said. One audience member asked whether
he was saying that performance properties should be considered part of a
program's correctness. Dwivedi agreed that he was: "Sometimes
performance-related behavior is as much a safety property as other properties, depending
on use.
"
Kernel code is reviewed with rigor; the same amount of care should be taken
with BPF code — and with the user-space code that it relies on to make decisions.
This is not something that the BPF subsystem can solve unilaterally, but the design of kernel interfaces can have an impact on how easy it is to model, test, and eventually verify useful properties of BPF programs. Frequently, kernel interfaces are not designed with static analysis in mind, and that is something that the BPF subsystem has to live with, he said. Still, there are improvements that can be made.
He gave bpf_obj_new() as an example of an interface that was a bad idea in hindsight. The motivation behind it was to let BPF programs compose their own data structures, but it implicitly inherited constraints related to handling the lifetime of kernel objects. Those constraints ended up propagating through the program, which made the API difficult to use. Simpler interfaces, that provide less flexible features but therefore require the verifier to perform fewer checks, are easier to work with.
Maybe the correct solution, he proposed, is to use different forms of automated program-verification in different areas. For example, Verus is a tool for automatically proving properties of Rust programs. Perhaps it could be used to handle properties that are critical to the overall function of a BPF program, but not to the safety of the kernel, per se. That is also a benefit to development speed: allowing early exploration before layering on additional safety once a solution has been identified.
To illustrate his point, Dwivedi talked through (without any actual code) how Verus could be used to prove that a scheduler has the property he proposed above: never leaving a CPU idle when a runnable task exists. The proof is based on work by researchers from Inria, the University of Sydney, and other institutions on formally verifiable scheduling. The core idea is to implement a simplified interface that is just powerful enough to accomplish the task in question, while still being amenable to formal verification. The simplified interface only has two queue-manipulation functions: push() and pop().
If one can prove that those two functions maintain the core invariant, and there is no other way to move tasks between queues, then no matter what the main scheduler logic does the invariant will be maintained. For push(), that is done by ensuring that, when asked to push a task onto a CPU's queue, either that CPU was already idle, or no other idle CPU exists. If there is an idle CPU, push() puts the task on its queue instead. The case for pop() is symmetrical. The original proof in the paper is more complicated, because it handles concurrency, but the overall structure of the proof is the same, Dwivedi said.
Alexei Starovoitov asked what it means for Verus to be a static-verification tool that operates on top of Rust. Dwivedi explained that the programmers behind Verus had previously worked on static analysis systems for other languages, but found it difficult, because those languages had many properties that made it hard to do local reasoning about program behavior, such as pointer aliasing. That made sense to Starovoitov, but he still wanted to clarify how Verus would interact with BPF.
The idea is that one would write a simplified Rust wrapper for the interface that a subsystem like sched_ext exposes, Dwivedi explained. That simplified wrapper would be annotated with Verus proofs about its behavior, which can be composed to cover the behavior of the whole program. Verus would check these proofs at compile time, rustc would produce BPF bytecode in the normal way, and then the in-kernel verifier would check the normal safety properties of BPF code. Starovoitov wasn't convinced that operating two separate static analysis pipelines in parallel would be doable, but agreed that he didn't see a problem with what Dwivedi was proposing so far.
Amery Hung asked what kinds of wrappers would be needed; Dwivedi explained that the answer would vary for different subsystems, but that sched_ext schedulers, for example, could likely share similar code. At that point the session ran out of time. It seemed that some BPF developers were unconvinced, but given that additional static verification can be adopted on a project-by-project basis, perhaps we will see more BPF programs analyzed by Verus or similar technologies.
Changes in shadow-utils password-expiration features
The shadow-utils project provides the tools that handle /etc/shadow, /etc/passwd, and other related databases; in general, it manages users and groups on many Linux systems. While most software releases are notable for what is added, the recent shadow-utils 4.20.0 release is most noteworthy for what has been removed. Specifically, several utilities and functionality related to periodic password expiry, which were deprecated in the December 2025 4.19.0 release, have been removed as planned. It is still possible to manage some aspects of password aging with shadow-utils, but organizations that depend on such features should start planning for their complete removal within a few years.
Some history
The shadow-utils project has its roots in the original Shadow Suite, written for SunOS in the 1980s, where /etc/shadow seems to have been invented. Password expiration wasn't supported as the old /etc/passwd database doesn't hold this information.
It's unclear when password-expiration features were added to the suite, but they are present in the first version committed to CVS in 1996. It seems likely they were added in the first version of the suite. Back then—and until very recently—it was common practice to periodically force password changes, as it was believed that it would decrease the risk of unauthorized access.
However, that belief no longer seems warranted. A paper
published in 2015, "Quantifying
the security advantage of password expiration policies" found that
the benefit of password expiry is "relatively minor at best, and
questionable in light of overall costs
".
In 2017, the US National Institute of Standards and Technology (NIST) published
an updated version (800-63B revision 3) of
its digital identity guidelines. Whether someone at NIST had read the paper is
unknown, but this revision recommended
against periodic password expiration. NIST published a FAQ in 2018 that explained
why it no longer recommended password expiration. If users know they will have
to change their passwords frequently, it said, "they often select a secret
that is similar to their old memorized secret by applying a set of common
transformations such as increasing a number in the password
". Thus, rotation
provided a false sense of security since attackers could likely predict how a
user might change their password.
In 2025, NIST published revision 4 of the publication, and strengthened the wording about periodic password expiration. This time, instead of recommending against password expiration, the policy prohibits it. Users are allowed to rotate passwords periodically, but the verifying software is not allowed to require this. The wording also changed from referring generically to arbitrary changes to specifically mentioning periodic changes.
Verifiers and CSPs SHALL NOT require subscribers to change passwords periodically. However, verifiers SHALL force a change if there is evidence that the authenticator has been compromised.
The changes in shadow-utils 4.20.0 move the project closer to today's best practices for password management by disabling some features that force password changes. The expiry command, which checks and enforces password-expiration policy, has been removed. This is a first step in shadow-utils deprecating and removing password-expiration features, and expiry was redundant with other programs as well. For example, it is possible to use getent to retrieve information about a user's password-expiration settings. A password can be expired immediately using passwd -e, which will force the user to reset the password on the next login.
The fourth field of /etc/shadow, which specifies the minimum number of days until a user can change a password, is now ignored and removed if present. There is no longer a minimum password age; it was a security vulnerability in some cases, and also part of deprecating and removing password-expiration features. It is a security vulnerability because it may have prevented users from changing their password immediately, which may be necessary if a user's password is compromised in some fashion.
Other changes
The groupmems command, which allowed users to administer the members of their own group, has been removed. Its functionality overlapped with the more powerful usermod command for root; since groupmems was not being installed as setuid root by distributions, it was useless for non-root users.
Support for the Data Encryption Standard (DES) and MD5 password-hashing algorithms has been removed, as they are insecure compared to more modern hashing algorithms. The default is now SHA512 if ENCRYPT_METHOD is not defined in the login.defs configuration file. However, other programs and libraries (such as libpam) also read this configuration file, and may still default to unsafe algorithms such as DES, so users should continue defining this variable explicitly, at least for some years.
The logoutd utility has been dropped. It was used to enforce login time and port restrictions as specified in the /etc/porttime configuration file. If that filename does not ring a bell, it is likely because it has not been used in some time; it is not mentioned in the Filesystem Hierarchy Standard's description of /etc, and none of the major Linux distributions package the logoutd utility these days—so it made sense to remove it from shadow-utils.
Outdated policies and workarounds
Some outdated policies still require password expiration. These policies, which are even required by some countries, are unfortunate. Some users we've spoken to are required by contract to expire their passwords, and shadow-utils must support them (or we'd force them to fork the programs, or worse).
While researching whether shadow-utils could remove password expiration, the maintainers found that Spain's National Intelligence Centre (CNI) has a policy requiring expiration, and it provides scripts using chage—among other programs—that set up systems to comply with its policies. These scripts are public, and are meant to be used by companies that must follow its policies. The maintainers of shadow-utils tried to contact CNI, but have not received an answer.
Several features related to password aging still remain in shadow-utils, but are deprecated and will be removed at a later date. For example, chage is still included, but several of its options for setting minimum password age have been removed and others are deprecated. The passwd, useradd, and usermod options related to aging of passwords are also deprecated.
Some fields of /etc/shadow cannot be removed yet, as explained above, as they are required by some policies and countries. However, they are deprecated, and will be removed eventually. This includes the third (date of last password change), fifth (maximum password age), sixth (password warning period), and seventh (password inactivity period) fields of /etc/shadow, and also the command options that handle these fields.
Users will not be able to enforce a minimum password age in shadow-utils 4.20.0 anymore, and there's no workaround for that. It is expected that the deprecated features will be supported for at least a few years, but organizations that have policies requiring unnecessary periodic password changes should plan to phase them out. It is our hope that removing these features will encourage better password policies and improve security.
[ Alejandro is one of the maintainers of the shadow-utils project. ]
Block-layer error injection
Storage code has to cope with hardware that fails in inconvenient ways, but coaxing a healthy disk into producing those failures on demand, for testing, is usually not possible. The kernel provides several ways to inject block-layer I/O errors, but none of those can select the operation to fail, pick the status code to return, or target a disk directly without employing a stacked device on top. Use of a stacked device means the test runs against the mapper device, not the disk it was meant to exercise. A patch series from Christoph Hellwig adds a configurable error-injection interface that does all three things that the current error-injection code lacks, controlled by a per-disk debugfs file.
Existing methods
The kernel has had a form of block-layer fault injection since 2006, when Akinobu Mita added fault-injection infrastructure. The block-layer portion (called fail_make_request) exposes debugfs knobs for controlling the probability, interval, and number of times that a fault will be injected. Its shortcoming is that it treats every request the same. It cannot tell a read from a write or a discard, cannot restrict failures to a range of sectors, and can only fail a request with BLK_STS_IOERR. The failure happens in submit_bio_noacct(), before the request reaches the driver. The filesystem or other kernel code that submitted the bio structure representing the request sees -EIO. If nothing retries the request on the way up, user space sees EIO from the system call. A single status is limiting for a subsystem in which a media error, a transport error, and a timeout each take a different path through the recovery code.
A second fault-injection mechanism, should_fail_bio(), was added by Howard McLauchlan in 2018 as a hook for BPF programs. That function is annotated with ALLOW_ERROR_INJECTION(), so the kernel's error-injection framework allows BPF programs to override the return value. Before that change, the bio submission path called should_fail_request() to determine whether an error return should be injected and passed only the disk device and a byte count. It now calls should_fail_bio() instead, which takes the bio and calls should_fail_request(), so the older feature behaves as before until a BPF program overrides the call. Such a program can read the bio and decide, for each request, whether to fail it based on the operation type or the sectors involved. That gives should_fail_bio() the selectivity that fail_make_request lacks.
The approach has a limitation, though. BPF programs can only replace a return value. A program can select which bio to fail, but not how it fails: submit_bio_noacct() ignores the value returned and completes the bio with BLK_STS_IOERR either way.
The device-mapper subsystem offers the other common approach, in the form of targets built to fail I/O requests. The simplest, dm-error, maps a region that returns an error for every request it receives. Like fail_make_request, it can produce only BLK_STS_IOERR, and it fails every command routed through the target regardless of operation or sector. To inject failures into I/O requests made to an existing device, a dm-error target must be stacked over that device. The test is then directed at the resulting mapper device, not the device that needs testing.
The dm-flakey and dm-dust targets are more configurable, and can, for example, fail I/O requests intermittently or emulate individual bad sectors. They still share the limitations that matter here: no real choice of error status and no good handling of commands other than reads and writes (such as zone operations or discards). Being device-mapper targets, they are also bound by the alignment rules that device-mapper imposes on the sector ranges a target may cover. dm-dust does not support zoned devices at all, while dm-flakey, like any zoned-capable target, can only confine failures to a whole-zone-aligned region, since a target's range must begin and end on a zone boundary. And, like dm-error, they require a stacked block device on top of the device under test.
The proposed mechanism
Hellwig's proposal, enabled through the new CONFIG_BLK_ERROR_INJECTION Kconfig option, takes a more direct route. When it is turned on, the block layer creates an error_injection file in debugfs, under /sys/kernel/debug/block/, for every registered gendisk. Reading the file lists the injection entries in effect for that disk; writing to it either adds a rule or, with a removeall command, clears every rule for the disk. The series documents the format in Documentation/block/error-injection.rst.
An entry is a short, comma-separated string. Two of its fields are mandatory: op, the operation to fail, taken from the block layer's operation names (READ, WRITE, DISCARD, the zone operations, and so on), and status, the block-layer status to return (IOERR, TIMEOUT, TRANSPORT, and so on). Three more are optional. A start sector and an nr_sectors count confine the failure to a range, leaving unrelated I/O requests to the same disk untouched; they default to sector zero and the remainder of the device, so that, without them, every request of the named operation type is a candidate. A chance value makes the failure probabilistic: with a value of N, a matching request fails with probability 1/N. It defaults to one, meaning the request always fails.
To fail one in every ten reads aimed at sectors 1000 through 1499 of nvme0n1 with a transport error, for example, a test would write:
    $ cd /sys/kernel/debug/block/nvme0n1
    $ echo 'add,op=READ,start=1000,nr_sectors=500,status=TRANSPORT,chance=10' > error_injection
Reading the same file back lists each active rule by its sector range, operation, status, and chance; the entry above appears as:
1000:1499 op=READ,status=TRANSPORT,chance=10
Implementation details
Almost all of the new code lives in a single file: block/error-injection.c. The hook into the I/O path sits in submit_bio_noacct_nocheck(), which calls blk_error_inject() for every bio before it is submitted. That inline function does nothing unless a static key is enabled; the first rule added on any disk turns it on. A per-disk GD_ERROR_INJECT bit narrows the work further to the disks that carry rules. Only then does the code drop into the out-of-line __blk_error_inject(). The static key was Jens Axboe's suggestion. Without it, every bio would dereference its way to a per-disk state bit that is almost always clear; with it, the branch is patched out entirely when injection is not in use.
__blk_error_inject() walks the target disk's list of rules under RCU, comparing each rule's operation against the bio, checking whether the sector ranges overlap, and, if a chance value was given, rolling a virtual N-sided die. The first rule that matches wins: bi_status is set to that rule's status, bio_endio() completes the bio, and submit_bio_noacct_nocheck() returns without submitting anything to the device. Because a new rule goes at the head of the list and the walk stops at the first match, a newer rule takes precedence over an older one covering the same I/O request; overlapping and even duplicate rules are allowed on purpose.
One case the matcher never fires on is the zero-length bio: the range test cannot match a bio that carries no sectors, so pure cache flushes and ZONE_RESET_ALL operations cannot be failed at all. A special case for them would be easy to add, but a pure flush reaches the block layer as an empty write carrying REQ_PREFLUSH rather than as an operation of its own, so every WRITE rule would start firing on flushes as well. As Hellwig noted in a code comment, making this work properly first requires the block layer to use REQ_OP_FLUSH for pure flushes at the bio level, as it already does in the blk-mq I/O scheduler; a rule could then target flushes directly.
Hellwig's implementation stays small and self-contained, reusing the existing per-disk debugfs infrastructure and not relying on other kernel subsystems. That simplicity was the core of his case against a more elaborate design.
BPF came up in the review as a possible foundation
for the mechanism itself; Daniel Gomez proposed a
BPF_PROG_TYPE_STRUCT_OPS hook that would keep only the
bio_endio_status() call in the kernel and move the matching
policy into a loadable program. Hellwig
rejected
the idea
as too much
machinery for the job. A program deciding which requests to fail has to
read the operation and the sector range out of the bio, and
exposing those through
BPF type format (BTF) (which is how BPF programs can access the internals of
kernel types) would turn the block layer's command and
status codes into a stable interface, Hellwig said, which he did not want
for internals that need to keep changing. Gomez
answered that
compile-once-run-everywhere relocations resolve field offsets against the BTF of
the running kernel, so a change in layout would not break an existing
program. That, Hellwig replied,
assumes the fields will still exist in that form at all; the
bio iterator is due for rework, and "we have to build up a
huge abstraction here first
".
A BPF hook would also require
libbpf and BTF support inside a test virtual machine. The sector
matching would move into the program as well, since Hellwig had found
no BPF map type suited to range lookups, so each range to be failed
would need code of its own, which he said
"makes the thing very hard
to use
". He had prototyped BPF-based injection
himself; as he put it, "it was a mess
", and he
preferred "about 300 lines of simple code that can be directly used
from a shell script
".
The patch adding the mechanism was merged for the Linux 7.2 release. Work has continued since. Hellwig fixed a static-key imbalance reported by Le Moal, then added a blktests test: block/044. It creates read and write rules over separate sector ranges, checks that the injected errors reach the caller, and confirms that malformed rules are rejected. The test also loads and unloads scsi_debug with no rules active, exercising the path behind the static-key fix. A later patch from Jackie Liu adding the affected operation to the output in debugfs landed in 7.2-rc4, producing the read-back format shown above. The bio-level flush change that would allow flushes to be failed has yet to appear. Still, users should look forward to expanded options for testing in Linux 7.2.
Page editor: Joe Brockmeier
Inside this week's LWN.net Weekly Edition
- Briefs: Django releases; GNOME shell; LightDM 1.33.0; QEMU 11.1; uutils 0.10; Software Stewardship Lab; Quotes; ...
- Announcements: Newsletters, conferences, security updates, patches, and more.